Section 1: Why Machine Learning Development Is Becoming an Automation Problem
Machine learning has become substantially easier to build than it was a decade ago, but developing a reliable production model still requires a long sequence of interconnected decisions involving data preparation, feature engineering, model selection, experimentation, evaluation, deployment, monitoring, and maintenance. Each stage can contain numerous alternatives, and the number of possible combinations can become extremely large as datasets, architectures, and operational requirements grow. This creates a fundamental engineering challenge because teams increasingly need to develop more models while keeping experimentation efficient, reproducible, and aligned with production requirements.
Autonomous machine learning emerges from this challenge by extending automation beyond individual tasks and toward systems that can coordinate multiple stages of the ML lifecycle, evaluate their own experiments, and determine which action should happen next.
The ML Development Lifecycle Contains Many Repetitive Decisions
A traditional machine learning workflow contains numerous decisions that are necessary but often repetitive, particularly when teams work across many related datasets or prediction problems. Engineers may need to test different preprocessing strategies, select features, compare algorithms, tune hyperparameters, evaluate multiple validation configurations, and repeat the process after data or requirements change. Although each decision can require expertise, a significant portion of the surrounding experimentation follows patterns that software can potentially automate.
Traditional AutoML systems already automate some of these activities by searching across candidate algorithms, hyperparameters, and preprocessing pipelines. The broader autonomous ML concept extends this approach by considering the state of the entire development workflow and using previous results to influence subsequent actions, which can allow the system to move beyond executing a predefined search toward coordinating an adaptive experimentation process.
The distinction becomes particularly important when the machine learning environment changes continuously. If a feature pipeline begins producing missing values, for example, an autonomous system could potentially detect the change, evaluate alternative preprocessing strategies, launch controlled experiments, and compare the resulting models against established performance and reliability criteria rather than simply executing the same pipeline again.
Increasing Model Complexity Makes Manual Coordination Harder
Modern ML systems are becoming more complicated because they increasingly combine multiple models, retrieval components, feature pipelines, embeddings, optimization layers, external tools, and monitoring mechanisms. This complexity expands the number of possible configurations and makes it difficult for teams to manually evaluate every reasonable alternative, especially when each experiment consumes substantial compute or requires coordination across different engineering systems.
The problem becomes even larger when organizations maintain many production models simultaneously, because every model can experience different data changes, performance requirements, and operational constraints. A team may need to decide which model should be retrained, which features should be investigated, whether a new architecture should be tested, or whether an underperforming model should be rolled back, making the ML lifecycle resemble a continuous decision process rather than a one-time development project.
This connects with “The Hidden Engineering Work Behind Every Successful Machine Learning Product,” because much of the effort required to maintain ML systems exists outside the model itself, including data pipelines, experiments, monitoring, deployment coordination, and operational maintenance.
Feedback Can Turn Automation Into Adaptive Development
Basic automation executes predefined instructions, whereas autonomous machine learning requires feedback from the outcomes of previous actions. If a system can observe that one experiment improves a target metric while another introduces unacceptable latency, it can use those observations to determine which direction deserves additional exploration, allowing subsequent experiments to become increasingly informed by accumulated evidence.
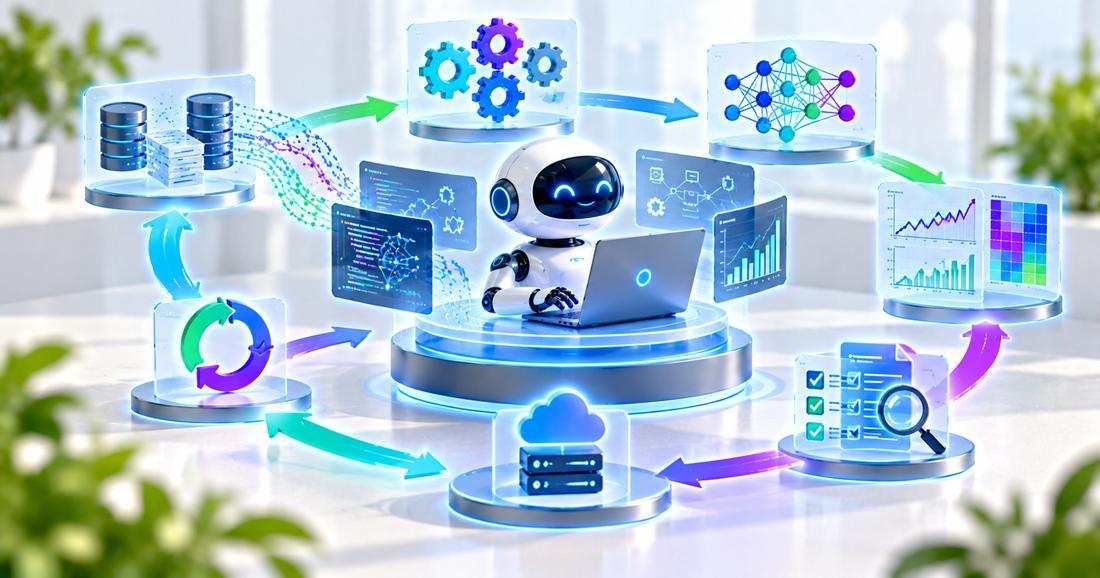
This creates a feedback loop in which the system proposes an action, executes the action, measures the result, updates its understanding of the available options, and selects another action based on the new information. In a mature implementation, the loop could extend across data preparation, model training, evaluation, deployment, and monitoring, creating an ML development environment that adapts as evidence accumulates.
However, the usefulness of such autonomy depends heavily on how the feedback signals are defined. If the system optimizes only for predictive accuracy, it may select a model that is too expensive to serve, too slow for the application, or unstable under distribution shift, which means autonomous optimization must consider the broader objective of building a model that is effective within its actual operating constraints.
Automation Does Not Remove the Need for Engineering Judgment
Greater autonomy does not imply that every ML decision should be delegated to software, because some decisions depend on business context, domain knowledge, safety requirements, or strategic considerations that may not be captured by historical metrics. An autonomous system can efficiently search a large space of technical alternatives, but it may not know that a particular feature is legally restricted, that a false positive has disproportionate operational consequences, or that a seemingly favorable optimization target conflicts with an important business objective unless those constraints are explicitly represented.
This makes the boundary between automation and human oversight an important part of autonomous ML architecture. Routine experimentation and well-defined operational decisions can potentially be automated, while high-risk changes, ambiguous failures, or changes outside established operating boundaries can be escalated for human review, creating a model in which automation increases engineering leverage without eliminating accountability.
Key Takeaway
Machine learning development is becoming an automation problem because modern workflows contain large numbers of repetitive decisions, increasingly complex model and infrastructure combinations, and continuous changes that require repeated experimentation. Autonomous machine learning extends traditional automation by using feedback from experiments and production behavior to determine what should happen next, but effective autonomy requires well-defined objectives, operational constraints, reproducible workflows, and human oversight for decisions that depend on context or carry significant consequences.
Section 2: How Autonomous ML Systems Automate Data, Experiments, Models, and Optimization
Autonomous machine learning systems can automate more than model selection by coordinating multiple stages of the ML lifecycle and using the results of previous actions to determine what should happen next. Instead of treating data preparation, experimentation, training, evaluation, and optimization as independent activities executed manually, an autonomous system can connect them through feedback loops that allow each stage to influence subsequent decisions.
The practical objective is not unrestricted automation, but the creation of a controlled system that can search through technical alternatives, identify promising configurations, and continuously improve its understanding of which approaches work under defined constraints.
Automating Data Preparation and Feature Engineering
Data preparation is often one of the most repetitive parts of machine learning development because engineers need to inspect schemas, detect missing values, identify unusual distributions, transform variables, encode categorical fields, and create representations that are suitable for a particular modeling task. Autonomous ML systems can automate portions of this process by profiling incoming data, identifying changes from previously observed distributions, testing candidate transformations, and evaluating whether those transformations improve downstream model performance.
Feature engineering can also become an adaptive search problem, particularly when the system has access to reusable transformations and a well-defined evaluation objective. An autonomous pipeline could generate candidate features, train controlled experiments, compare their contribution against a baseline, and retain only transformations that provide measurable value under the specified validation criteria, which can reduce the amount of manual experimentation required while preserving a structured record of what was tested.
The larger opportunity is to connect data-quality monitoring with feature generation so that a change in the underlying data can trigger targeted investigation rather than forcing the entire workflow to restart manually.
Automating Experiment Design and Model Search
Once candidate datasets and feature representations are available, an autonomous system can search across model architectures, hyperparameters, training strategies, and other configuration choices. Traditional hyperparameter optimization already automates part of this process, but a broader autonomous system can combine experiment results with knowledge about resource budgets, previous failures, and production requirements to decide which experiment should be executed next.
This creates a sequential optimization problem in which every experiment produces information that changes the value of future experiments. If one architecture performs well but exceeds the latency budget, the system can prioritize alternatives that preserve similar predictive quality at lower computational cost, while an approach that consistently underperforms can be deprioritized so that compute is not wasted on repeated variations of an unpromising configuration.
The quality of this search depends heavily on the objective function because optimizing a single metric can lead the system toward undesirable solutions. An autonomous ML platform may therefore need to optimize predictive performance together with latency, memory usage, training cost, fairness constraints, robustness requirements, and other operational objectives, which makes the search process closer to constrained engineering optimization than simple hyperparameter tuning.
Automating Evaluation and Model Selection
An autonomous ML system needs reliable mechanisms for determining whether a newly trained model is actually better than the current alternative, because automated experimentation becomes dangerous when weak or misleading evaluation signals are treated as ground truth. A mature evaluation layer can compare candidate models against strong baselines, test multiple data slices, measure robustness under controlled perturbations, and verify that production constraints remain satisfied before a candidate is considered eligible for deployment.
The system can also use progressive evaluation strategies to conserve resources, because there is little value in performing expensive testing on models that already fail inexpensive checks. A candidate might first undergo schema validation and basic performance testing, then move to more comprehensive evaluation if it satisfies those conditions, and only the strongest candidates might receive expensive stress testing or shadow deployment.
This creates an important distinction between automated experimentation and automated acceptance, because the system can generate and evaluate many candidates without necessarily granting every successful experiment permission to become a production model. Deployment eligibility can remain subject to explicit gates that encode reliability, safety, governance, and operational requirements.
The same architecture can support continuous re-evaluation after deployment by comparing live behavior with historical performance and identifying whether the model remains within its expected operating envelope. As discussed in “From Experiment to Production: The Decisions That Shape an ML System,” the transition from experimental success to production readiness requires decisions that account for the environment surrounding the model, and autonomous ML systems need those considerations to remain embedded in the automation loop.
Key Takeaway
Autonomous machine learning can automate data preparation, feature engineering, experiment selection, model evaluation, and lifecycle optimization by connecting these stages through feedback-driven decision loops. The most effective systems do not simply run more experiments; they use previous results, production signals, resource constraints, and explicit acceptance criteria to determine which actions deserve further attention. This turns ML automation from a collection of isolated tools into a coordinated development system that can continuously search, evaluate, and improve models while remaining within defined technical and operational boundaries.
Section 3: Designing Autonomous Machine Learning Systems That Remain Reliable and Controllable
Autonomous machine learning can reduce repetitive engineering work, but increasing the number of decisions made by software also increases the consequences of incorrect decisions. A system that can automatically modify features, launch experiments, retrain models, and prepare deployments can move much faster than a manually coordinated workflow, but it can also repeat a flawed assumption at much greater scale if its objectives, validation mechanisms, or control boundaries are poorly designed. Reliable autonomous ML therefore requires an architecture in which experimentation and adaptation are encouraged inside clearly defined limits.
Establish Explicit Objectives, Constraints, and Decision Boundaries
The first requirement for autonomous ML is a precise definition of what the system is allowed to optimize because predictive accuracy alone is rarely sufficient for a production model. A system may discover a model with excellent validation performance while creating unacceptable latency, excessive inference costs, unstable behavior on minority segments, or poor performance under distribution shift, so the optimization objective should combine the metrics that actually define success for the application.
Constraints are equally important because some requirements should not be treated as optimization preferences. A production model may need to remain below a specific latency threshold, operate within a fixed compute budget, satisfy data-retention requirements, or maintain minimum performance across critical segments, and an autonomous system should reject candidate solutions that violate such conditions even when their aggregate performance appears attractive.
Decision boundaries also need to specify which changes can happen automatically and which require human approval. Routine hyperparameter searches or low-risk retraining actions may be suitable for automation, while changes to sensitive features, model behavior with significant business consequences, or modifications to safety-critical workflows may need explicit review, allowing autonomy to increase engineering leverage without turning every ML decision into an uncontrolled action.
Build Reproducibility and Evaluation Into Every Automated Action
Autonomous experimentation can generate a large number of model versions, preprocessing configurations, datasets, and evaluation results, which makes reproducibility essential because engineers need to determine exactly why a system selected one approach instead of another. Every automated action should therefore produce traceable information about the input data, code and pipeline versions, model configuration, resource usage, evaluation environment, and decision criteria that influenced the outcome.
Evaluation also needs to be layered because a single benchmark score can encourage an autonomous system to exploit weaknesses in the evaluation process rather than improve the actual model. A candidate can first pass inexpensive checks for schema compatibility, basic predictive performance, and resource limits, after which stronger candidates can undergo slice-based testing, robustness analysis, stress testing, and shadow evaluation against realistic production traffic.
The system should also maintain strong baselines because autonomous search can create the illusion of progress when successive experiments are only being compared with weak or outdated alternatives. A candidate should demonstrate measurable improvement over the current production system or a credible reference model, while changes in business or data conditions should trigger re-evaluation of whether the baseline itself remains appropriate.
This approach connects with “The Reproducibility Crisis in Machine Learning: What Engineering Teams Can Do,” because autonomous development increases the number of experiments and model transitions, making lineage, traceability, and repeatable evaluation even more important than they are in manually managed workflows.
Control Resources, Deployment, and Feedback Loops
Autonomous ML systems can consume substantial computational resources because their ability to launch experiments may otherwise become limited only by the number of available configurations, making experiment budgeting an essential part of the architecture. Training budgets, early stopping, prioritization, hardware allocation, and expected-value thresholds can help the system concentrate resources on experiments that have a reasonable chance of producing meaningful improvements rather than continuously exploring low-value alternatives.
Deployment requires similar controls because an automatically selected model should not immediately replace a production system merely because it wins an offline comparison. Shadow deployment, canary releases, automated rollback, and post-deployment monitoring can allow the system to validate whether a candidate behaves as expected under real traffic before granting it broader authority, while explicit rollback conditions can prevent a rapidly degrading model from remaining active simply because its offline metrics looked strong.
Feedback loops also need careful design because autonomous systems can change the environment they are measuring. A recommendation model can alter user behavior, a pricing model can influence demand, and an automated retraining process can change the population represented in subsequent training data, so a system that blindly learns from its own interventions may reinforce temporary effects or gradually optimize toward artifacts created by its previous decisions.
This makes production monitoring a source of evidence rather than an automatic command to retrain. A change in data distribution may indicate a legitimate environmental shift, an upstream pipeline problem, or an effect caused by the model itself, and the autonomous system should distinguish among these possibilities before selecting the next intervention.
Keep Humans in the Loop Where Context Matters
Autonomous ML should not be understood as the elimination of human expertise because some decisions require information that is difficult to encode completely in automated objectives. Engineers and domain experts may know that a feature is subject to contractual restrictions, that a particular business period should not be used for model comparison, or that an apparently small model change could have consequences not visible in historical metrics, making human context essential for certain parts of the lifecycle.
A practical architecture can therefore divide decisions into different levels of autonomy. Low-risk experimentation can proceed automatically within defined budgets and constraints, model candidates can pass through automated validation and staged deployment, and high-impact changes can be routed to human reviewers who can approve, reject, or modify the proposed action.
The system can also learn from human interventions by recording why a candidate was rejected or why a particular operational choice was preferred, provided those explanations are captured in a way that can be audited and used appropriately in future experimentation.
This creates a more useful definition of autonomy in which the system becomes capable of managing routine technical complexity while humans remain responsible for decisions that depend on organizational context, unusual risk, or ambiguous objectives.
Key Takeaway
Reliable autonomous machine learning requires explicit objectives, hard constraints, reproducible experimentation, layered evaluation, controlled resource usage, staged deployment, feedback-loop monitoring, and well-defined human intervention points. The goal is not to create systems that change themselves without oversight, but to build ML infrastructure that can safely automate routine development and optimization while preserving traceability, operational control, and human judgment where the consequences of automation are harder to measure.
Section 4: Why Autonomous ML Could Transform the Future of AI Engineering
Machine learning is increasingly becoming a continuous engineering process rather than a project that ends when a model reaches production. Data changes, user behavior evolves, infrastructure requirements shift, new models become available, and production performance can gradually deteriorate, which creates a growing need for systems capable of monitoring, experimenting, adapting, and improving ML applications without requiring engineers to manually coordinate every step.
Autonomous machine learning could become an important response to this complexity because it extends automation from individual development tasks toward a broader system capable of coordinating parts of the machine learning lifecycle and determining which actions are most useful under defined constraints.
From Automated Pipelines to Self-Optimizing ML Systems
Traditional ML pipelines are usually designed around a sequence of predefined operations in which data is processed, a model is trained, evaluations are performed, and a deployment process is initiated when explicit conditions are satisfied, while autonomous systems can potentially make decisions about which pipeline actions should occur based on observed evidence from previous experiments and production behavior.
This creates a transition from static automation toward self-optimizing ML systems, where the system continuously evaluates whether its current configuration remains appropriate and searches for alternatives when evidence suggests that improvement is possible. A model experiencing distribution shift, for example, might trigger targeted data analysis, candidate feature generation, retraining experiments, and comparative evaluation rather than simply following a fixed retraining schedule.
The broader opportunity is that the ML platform becomes capable of managing more of the reasoning around development itself, which can reduce repetitive engineering work while allowing teams to allocate their attention toward architecture, domain-specific problems, and decisions that require broader organizational context.
Autonomous ML Can Make Continuous Improvement More Practical
Production machine learning systems generate a continuous stream of information about their own behavior, including prediction distributions, latency, resource consumption, error patterns, user interactions, and business outcomes, and an autonomous system can potentially use these signals to identify opportunities for improvement and prioritize the experiments most likely to produce meaningful gains.
For example, if monitoring shows that a model's performance is declining only for a specific segment, the system could investigate that segment rather than retraining the entire model blindly, while a change in input distributions without corresponding performance degradation might trigger additional observation instead of immediate intervention. This distinction can reduce unnecessary experimentation and help align automated actions with evidence rather than simple threshold triggers.
The same principle can support resource-aware experimentation because autonomous systems can evaluate the expected benefit of running an experiment against its computational cost, which becomes increasingly important when organizations operate large numbers of models and cannot afford unlimited automated experimentation.
This creates a connection with “Resource-Aware Machine Learning: Designing Models Around Compute and Energy Limits,” because the future of autonomous ML will depend not only on whether systems can discover better models, but also on whether they can determine which experiments and interventions are worth the resources they consume.
Autonomous ML Could Reshape the Role of ML Engineers
Greater automation is unlikely to eliminate the need for machine learning engineers because the most important responsibilities may increasingly move toward defining objectives, establishing system boundaries, designing evaluation frameworks, and ensuring that autonomous behavior remains aligned with technical and organizational requirements.
Instead of spending substantial time manually running repeated experiments, engineers may increasingly focus on determining what the autonomous system should optimize, which constraints cannot be violated, which datasets and evaluation strategies are trustworthy, and which categories of decisions require explicit human approval.
This can increase engineering leverage because one team may be able to supervise a larger portfolio of models through a common autonomous infrastructure layer, while specialized human expertise remains available for ambiguous failures, architectural changes, and high-impact decisions.
The shift also creates a stronger need for observability and governance because engineers must be able to understand not only what a production model is doing, but why an autonomous system selected a particular experiment, rejected a candidate, initiated retraining, or decided that no intervention was necessary.
The Future Could Be Closed-Loop Machine Learning Development
The most ambitious form of autonomous ML would create a closed-loop development system in which data and production behavior continuously inform model improvement, allowing the platform to observe the environment, identify potential problems, generate candidate interventions, execute controlled experiments, evaluate outcomes, and update the production system when predefined evidence and safety conditions are satisfied.
Such a system could connect data-quality monitoring, feature engineering, model training, evaluation, deployment, and post-deployment monitoring into one continuous loop, while staged releases and rollback mechanisms would provide protection against automated changes that perform poorly under real-world conditions.
The resulting architecture would resemble an autonomous engineering control system in which machine learning models are continuously maintained rather than treated as static artifacts, but the reliability of this approach would depend on preventing feedback loops, objective drift, evaluation exploitation, and uncontrolled resource consumption.
The long-term significance is therefore not that machines will independently replace ML engineers, but that increasingly capable infrastructure could absorb more of the repetitive coordination required to build and maintain machine learning systems, allowing human expertise to concentrate on the decisions that require domain understanding, system-level reasoning, and accountability.
Key Takeaway
Autonomous machine learning could transform AI engineering by turning static ML pipelines into adaptive systems that continuously monitor performance, design experiments, optimize models, and respond to changes in data and production behavior. The most valuable future architecture will combine automation with explicit constraints, resource-aware experimentation, reproducibility, staged deployment, and human oversight, allowing ML systems to improve continuously without sacrificing reliability, accountability, or operational control.
Conclusion
Machine learning development has traditionally depended on a sequence of human-led decisions covering data preparation, feature engineering, model selection, experimentation, evaluation, deployment, monitoring, and retraining. As organizations operate larger numbers of models across increasingly complex environments, manually coordinating every stage becomes more difficult, which creates an opportunity for systems that can automate not only individual ML tasks but also the decisions connecting those tasks.
Autonomous machine learning represents this broader direction.
Rather than treating automation as a collection of independent tools, autonomous ML connects data monitoring, experimentation, model optimization, evaluation, deployment, and production feedback into a coordinated workflow that can determine which actions should happen next within predefined objectives and constraints.
The distinction from conventional AutoML is important because traditional AutoML generally focuses on automating specific parts of model development, while autonomous ML aims to create a more continuous system that can observe its environment, evaluate evidence, initiate experiments, compare alternatives, and respond to production changes with progressively less manual coordination.
This does not mean that humans disappear from the machine learning lifecycle.
Human expertise remains essential because many important decisions depend on business context, domain knowledge, safety requirements, organizational priorities, and consequences that cannot be fully represented through historical metrics. The most practical architecture is therefore likely to automate routine technical decisions while reserving high-impact, ambiguous, or context-dependent decisions for human review.
Autonomous ML also changes the importance of evaluation.
A system that can generate and test large numbers of models can easily optimize the wrong objective if evaluation is poorly designed. Accuracy alone may encourage solutions that are expensive, slow, unstable, difficult to maintain, or unreliable under distribution shift. Autonomous systems therefore need multi-dimensional objectives that account for predictive performance, resource consumption, latency, robustness, fairness where relevant, and operational constraints.
Frequently Asked Questions
1. What is autonomous machine learning?
Autonomous machine learning refers to systems that can automatically perform and coordinate multiple stages of the ML lifecycle, using experiment results and production signals to determine which actions should happen next while operating within predefined objectives and constraints.
2. How is autonomous ML different from AutoML?
AutoML commonly automates specific activities such as model selection, hyperparameter optimization, or pipeline construction, while autonomous ML aims to coordinate a broader lifecycle that can include data monitoring, experimentation, evaluation, deployment, and post-production adaptation.
3. Can autonomous machine learning build models without human involvement?
It can automate many routine development activities, but completely removing humans is generally unnecessary and potentially risky. High-impact decisions, unusual failures, business-context questions, and changes that exceed established boundaries can remain subject to human review.
4. What parts of ML development can be automated?
Automation can cover data profiling, preprocessing, feature generation, experiment design, hyperparameter optimization, model selection, evaluation, deployment preparation, monitoring, retraining decisions, and resource allocation when these activities have clearly defined objectives and validation criteria.
5. How does an autonomous ML system decide what to do next?
The system can observe the current state of the ML workflow, examine previous experiment results and production signals, evaluate available actions against defined objectives and constraints, and select the next action based on its expected value.
6. Why are feedback loops important in autonomous machine learning?
Feedback loops allow an autonomous system to learn from the results of previous actions, because experiment outcomes, model performance, data changes, and production behavior can provide evidence that influences subsequent decisions and makes the development process adaptive rather than strictly predetermined.
7. What risks are associated with autonomous ML?
Important risks include optimizing the wrong objective, repeatedly learning from biased or corrupted data, consuming excessive compute, deploying a weak model too quickly, creating feedback loops, exploiting weaknesses in evaluation metrics, and making changes that have consequences not captured by automated measurements.
8. How can organizations control autonomous ML systems?
Organizations can establish explicit optimization objectives, hard constraints, experiment budgets, deployment gates, approval thresholds, audit trails, staged releases, rollback mechanisms, and human-review requirements for decisions that carry significant operational or business consequences.
9. Why is reproducibility important for autonomous ML?
Autonomous systems may generate many experiments and model versions, so reproducibility allows engineers to determine which data, configuration, code, evaluation environment, and decision criteria produced a particular result and makes automated behavior easier to audit and debug.
10. Can autonomous ML optimize model cost as well as accuracy?
Yes, provided cost and resource consumption are explicitly represented in the optimization objectives. A system can evaluate predictive quality alongside latency, memory usage, training compute, inference cost, energy consumption, or other operational constraints when selecting among candidate models.
11. Can autonomous ML retrain models automatically?
Yes, an autonomous system can monitor production data and model behavior and initiate retraining when predefined evidence indicates that additional training is justified, although the trigger should distinguish genuine model degradation from temporary anomalies or upstream data-quality problems.
12. What is the role of human engineers in autonomous ML?
Human engineers increasingly focus on defining objectives, constraints, evaluation strategies, architecture, governance, and system boundaries while automated infrastructure handles repetitive experimentation and lifecycle coordination, allowing human expertise to concentrate on decisions that require domain knowledge and broader context.
13. How can autonomous ML avoid deploying a bad model?
Systems can use layered validation, strong baselines, scenario-based testing, shadow deployment, canary releases, production monitoring, explicit acceptance thresholds, and automated rollback so that an offline experiment does not automatically become a broad production change.
14. Is autonomous ML suitable for every machine learning application?
No, because the appropriate level of autonomy depends on model risk, decision reversibility, operational complexity, data quality, and the ability to define reliable objectives. High-impact or poorly understood applications may require substantially more human oversight than routine, well-bounded ML workflows.
15. What is the future of autonomous machine learning?
Autonomous ML is likely to evolve toward closed-loop systems that continuously monitor data and model behavior, design targeted experiments, optimize model configurations, manage deployments, and adapt to changing environments while using explicit safety boundaries, resource controls, reproducibility mechanisms, and human oversight for high-impact decisions.