Section 1: Why Multimodal Data Pipelines Are Fundamentally Different From Traditional ML Pipelines
Multiple Data Types Create Different Engineering Requirements
Traditional machine-learning pipelines are often designed around structured datasets in which features share relatively consistent formats, schemas, storage patterns, and preprocessing requirements. Multimodal machine learning changes that assumption because a single application can depend on text, images, audio, video, sensor readings, structured records, and behavioral events simultaneously. Each modality has fundamentally different characteristics, meaning that engineers cannot simply place every input into one generic preprocessing pipeline without losing important information or creating inconsistent representations.
Text is sequential and highly dependent on linguistic context, images contain spatial relationships, audio carries temporal patterns, video combines visual and temporal information, and sensor data may arrive continuously at varying frequencies. Structured records introduce another class of requirements because schemas, categorical values, numerical fields, and relational dependencies need explicit validation. These differences affect ingestion, serialization, preprocessing, storage, feature extraction, and inference, making multimodal data engineering substantially more complex than extending a conventional tabular pipeline.
The challenge becomes more pronounced when modalities are generated by different systems because the data may arrive at different rates and under different reliability guarantees. A camera can produce a continuous stream of frames while application metadata arrives only when an event occurs, and an audio stream may have to be segmented differently from the corresponding visual or sensor data. Engineers therefore need modality-specific processing pipelines that eventually converge into a representation suitable for the downstream machine-learning system.
Synchronization Becomes a Core Data-Engineering Problem
The defining challenge of multimodal data pipelines is often not simply collecting different data types, but ensuring that those data types refer to the same underlying event or context at the correct point in time. A self-driving system may need to associate a camera frame with lidar observations, vehicle telemetry, GPS coordinates, and control signals, while an enterprise application might need to connect a customer message with an uploaded image, account activity, and transaction history. Each input can be individually valid while the combined dataset becomes incorrect if the relationships among them are misaligned.
Timestamp consistency is therefore critical because different systems may use different clocks, sampling rates, delays, and event-time semantics. An image captured at one moment may be processed several milliseconds later, while a sensor measurement may arrive after network buffering or transmission delays. Engineers need mechanisms for preserving original event timestamps, distinguishing event time from processing time, and handling late or missing observations without silently associating information with the wrong context. The problem becomes even harder when one modality is continuous and another is event-driven, requiring explicit rules for defining how much temporal overlap is sufficient for the data to be considered related.
Synchronization also needs to account for spatial and contextual relationships because time alone may not establish that two observations describe the same event. A camera mounted on a vehicle, for example, may capture an object while a separate sensor detects another object within a similar time window, but geographic position, sensor orientation, and identity may be necessary to determine whether the observations should be combined. These relationships become part of the data model itself, making multimodal alignment an engineering problem that extends beyond conventional feature preprocessing.
Data Quality Must Be Evaluated Across Modalities and Relationships
Data-quality validation becomes more complicated when a machine-learning system depends on multiple modalities because each modality can fail independently while the complete pipeline continues operating. An image source may become unavailable while text metadata continues arriving, an audio stream may contain corrupted segments, or sensor readings may become stale while application events remain current. A pipeline that validates each source independently can therefore report healthy inputs even when the combined representation is incomplete or inconsistent.
Engineers need modality-specific validation as well as cross-modal validation. Image pipelines may check resolution, corruption, format, and exposure characteristics, while text pipelines may evaluate encoding, language, length, and missingness. Sensor streams may require range validation, sampling-frequency checks, and temporal continuity, while structured data may require schema and referential-integrity checks. These checks become more valuable when combined with relationship-level validation that determines whether required modalities are synchronized and sufficiently complete for a particular prediction.
Missing data also requires an explicit strategy because the absence of one modality does not always make inference impossible. A system may be designed to operate using a subset of available inputs, while another application may require all modalities before making a reliable decision. Engineers therefore need to distinguish between acceptable missingness and conditions that should trigger fallback logic, delayed processing, or an explicit prediction-quality warning. This principle aligns with “Machine Learning Without Perfect Data: Strategies for Real-World Datasets,” because multimodal systems require deliberate strategies for imperfect inputs rather than assuming that every production observation will contain complete and synchronized information.
Key Takeaway
Multimodal ML pipelines are fundamentally different from traditional ML pipelines because engineers must manage heterogeneous data formats, temporal and contextual synchronization, modality-specific and cross-modal quality, and increasingly complex lineage requirements. The central engineering challenge is not merely bringing more data into a model, but preserving the relationships among different forms of information so that the model receives a coherent representation of the real-world event it is expected to understand.
Section 2: How Engineers Build and Transform Multimodal Data for Machine Learning
Each Modality Requires Its Own Ingestion and Preprocessing Strategy
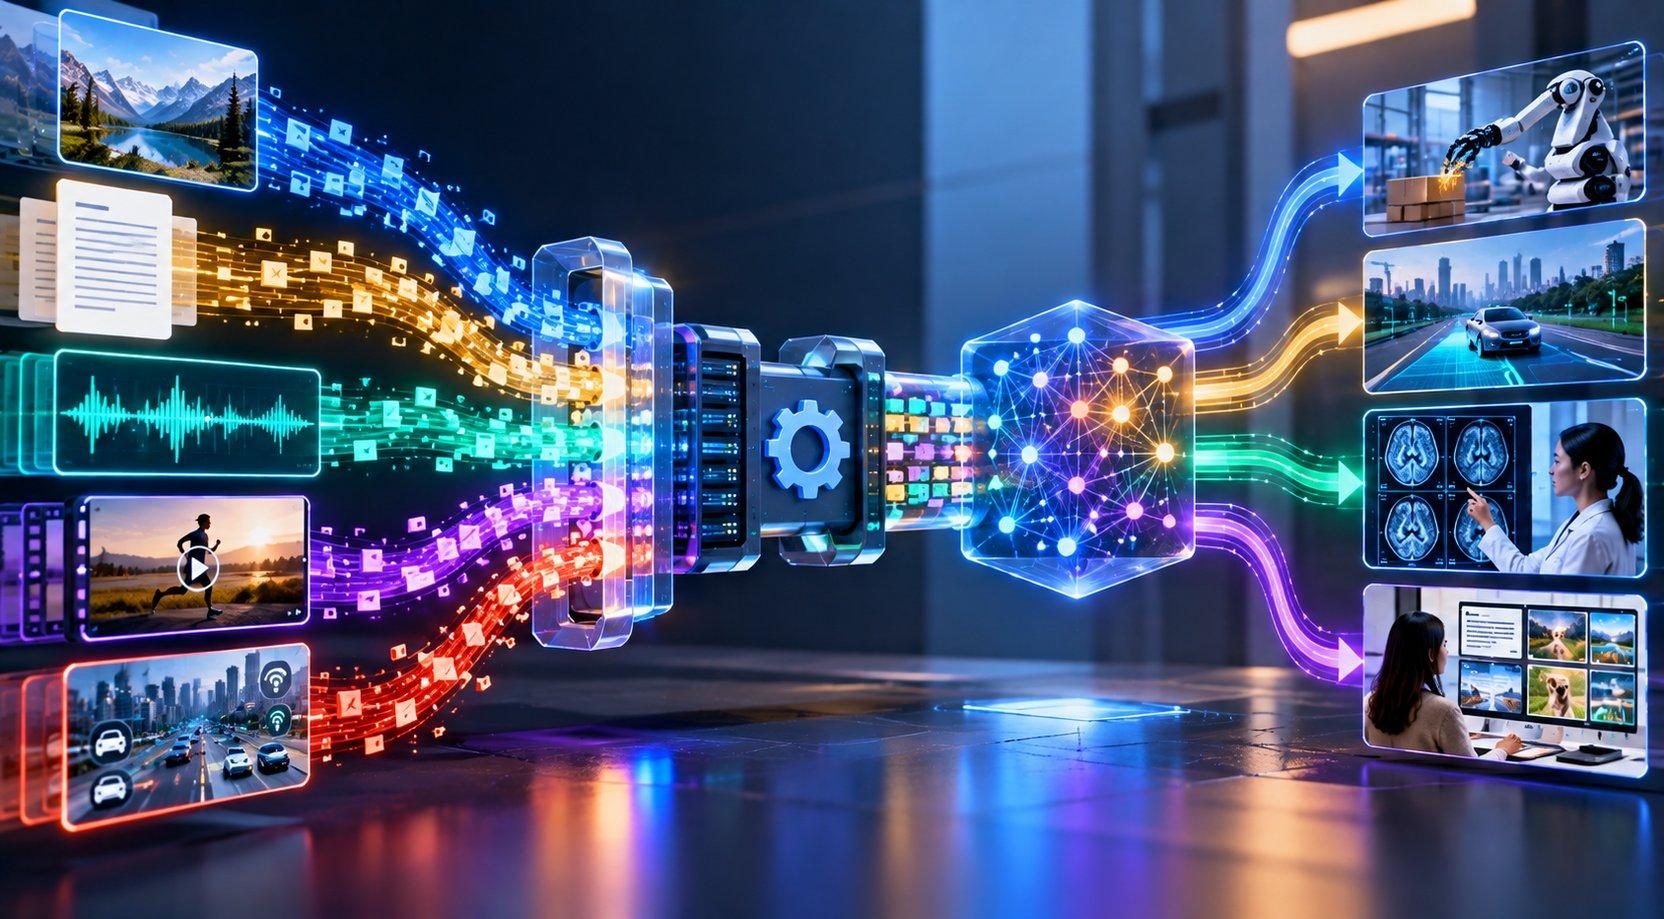
Building a multimodal ML pipeline begins with recognizing that different data types require different ingestion and preprocessing strategies because the assumptions that work for one modality can damage another. Text may need tokenization, normalization, language detection, and document segmentation, while images may require decoding, resizing, cropping, normalization, and quality checks. Audio introduces sampling rates, channels, segmentation, and noise characteristics, while video adds frame extraction, temporal sampling, compression, and potentially object or scene metadata. Structured data brings schema validation, type checking, joins, and categorical or numerical transformations that are fundamentally different from unstructured modalities.
This means engineers generally build modality-specific ingestion layers before creating a common downstream representation. Each layer can enforce the quality and structural requirements appropriate to the source while preserving metadata needed for later alignment. A video pipeline, for example, should retain frame timestamps and source identifiers, while an audio pipeline should preserve sampling information and segment boundaries. Maintaining this information during preprocessing is important because transformations that remove temporal or contextual metadata can make later synchronization substantially harder.
The preprocessing strategy must also consider downstream model requirements because different multimodal architectures consume data in different forms. Some models may operate directly on raw tokens or pixels, while others depend on embeddings generated by modality-specific encoders. Engineers therefore need pipelines that can produce consistent representations without discarding information required for later fusion. This makes preprocessing an architectural decision rather than a purely mechanical transformation step, reinforcing the importance of choosing representations that preserve the signal the model is expected to learn.
Shared Representations Connect Previously Separate Data Sources
Once each modality has been ingested and cleaned, engineers need mechanisms for connecting representations that originate from fundamentally different data spaces. Text embeddings encode semantic relationships, image embeddings represent visual features, and audio or sensor representations can capture temporal and physical patterns. A multimodal model can combine these representations through concatenation, cross-attention, joint embedding spaces, or other fusion mechanisms, but the quality of the result depends heavily on whether the underlying representations have been constructed consistently.
Shared representation spaces can be particularly useful when the objective is to establish relationships between modalities that previously existed independently. An image of a product can be connected to a textual description, an audio segment can be associated with a corresponding event label, and sensor measurements can be aligned with visual observations of the same physical process. The pipeline therefore needs stable identifiers and contextual metadata that allow representations to be linked without ambiguity.
Engineers also need to consider whether representations should be generated once and reused or produced dynamically during inference. Precomputed embeddings can reduce repeated computation for relatively stable content, while dynamic encoding may be necessary when the underlying information changes frequently. The choice influences storage, latency, freshness, and infrastructure costs, making representation management part of the broader ML platform architecture.
This connects naturally with “How ML Engineers Decide Which Features Are Worth Keeping,” because multimodal systems can generate a large number of candidate representations, and retaining everything can increase storage and computational requirements without necessarily improving model quality. Engineers therefore need to evaluate which representations contribute meaningful predictive signal and which can be removed, compressed, or generated only when required.
Feature Stores Are Evolving Into Multimodal Data Infrastructure
Traditional feature stores were designed primarily around structured numerical and categorical features used by predictive models, but multimodal systems require broader infrastructure because the useful representation may be an image embedding, document vector, audio representation, video segment, sensor window, or combination of several modalities. This creates a need for data systems that can manage heterogeneous representations while preserving metadata, timestamps, lineage, freshness, and relationships between related objects.
A multimodal feature platform must also address different storage and retrieval characteristics because an embedding vector, an image object, and a time-series segment have different access patterns and resource requirements. Engineers may need object storage for large raw artifacts, vector indexes for embeddings, relational or key-value systems for metadata, and streaming infrastructure for continuously changing signals. The challenge is creating a logical layer through which downstream models can retrieve the appropriate representations without requiring every application team to understand the underlying storage architecture.
Freshness becomes particularly important when multimodal features are generated from changing information. A customer profile embedding may remain valid for hours, while a real-time behavioral signal may need to be updated seconds before inference. A sensor representation may become stale almost immediately if the physical environment is changing rapidly. The infrastructure therefore needs modality-specific freshness policies rather than treating every feature as equally persistent.
Key Takeaway
Building multimodal ML pipelines requires modality-specific preprocessing, shared representation management, broader feature infrastructure, and training systems that preserve relationships across heterogeneous inputs. The central engineering objective is to transform independently generated data into synchronized, traceable, and model-ready representations without losing the temporal, spatial, semantic, or contextual relationships that make multimodal learning valuable.
Section 3: Making Multimodal Data Pipelines Reliable at Production Scale
Storage and Compute Requirements Increase Rapidly With Multiple Modalities
Production multimodal systems can generate dramatically more data than conventional machine-learning pipelines because each real-world event may produce several large and independently evolving artifacts. A single video stream can generate thousands of frames, associated audio can add another continuous data source, sensor systems can produce high-frequency numerical measurements, and application metadata can add documents, identifiers, and transactional context. Storing these inputs together therefore requires an architecture that separates raw data, processed representations, metadata, and frequently accessed features while still preserving the relationships among them.
Object storage is often useful for large raw assets such as images, videos, audio recordings, and documents, while structured databases can manage metadata, identifiers, timestamps, and relationships between records. Vector infrastructure can store embeddings generated by modality-specific encoders, and streaming systems can handle continuously arriving sensor or event data. The engineering challenge lies in connecting these layers without creating excessive data movement or inconsistent versions, particularly when inference requires several modalities within a strict latency budget.
Compute requirements also increase because multimodal inference may involve multiple encoders before a fusion model can generate its final output. An image encoder, text encoder, audio processor, and sensor-processing component can each consume substantial compute before the main model even begins its reasoning stage. Engineers therefore need to determine which representations should be precomputed, which should be generated on demand, and which transformations can be shared across applications. Efficient caching, batching, asynchronous preprocessing, and selective computation can reduce the cost, while hardware-aware optimization becomes increasingly valuable when multimodal workloads operate at high volume.
Versioning and Reproducibility Become More Difficult Across Data Types
Reproducibility becomes considerably more complicated when a model depends on several data modalities because each input can have its own preprocessing logic, transformation history, and version lifecycle. A training example may depend on a specific image transformation, audio segmentation strategy, text tokenizer, sensor normalization method, synchronization rule, and embedding model, meaning that reproducing the same model input requires more than retrieving the original raw files.
Versioning therefore needs to cover the full multimodal pipeline rather than the final model artifact alone. Engineers may need to record source-object versions, preprocessing configurations, encoder versions, synchronization policies, filtering decisions, dataset definitions, and feature-generation jobs so that a training sample or production prediction can be reconstructed later. Without this information, a model may appear reproducible at the software level while producing different results because one upstream modality was processed differently.
This challenge becomes especially important when data pipelines evolve independently. A new image preprocessing algorithm may improve visual representations while changing the input distribution expected by a previously trained fusion model, while an updated audio encoder can change embedding characteristics without any modification to the downstream architecture. Pipeline changes therefore need compatibility testing and clear lineage so that engineers understand which model versions depend on which data-processing components.
These requirements reinforce the principles described in “The Reproducibility Crisis in Machine Learning: What Engineering Teams Can Do,” because reproducibility in multimodal systems depends on recording not only model parameters but also the complete chain of transformations that created the model's inputs. Strong lineage allows engineering teams to reproduce experiments, investigate regressions, compare datasets, and understand whether a performance change originated in the model or in one of the upstream modality pipelines.
Missing or Misaligned Modalities Require Graceful Fallbacks
A production multimodal system cannot assume that every expected input will always be available because individual sensors, APIs, data sources, or preprocessing services can fail independently. A camera may produce no usable frame, an audio stream may be interrupted, a document may be unavailable, or a sensor may report stale values while other modalities continue operating normally. The resulting system needs explicit policies for determining whether prediction can continue with partial information or whether the request should be delayed or rejected.
Graceful fallback strategies allow systems to remain useful when complete multimodal context is unavailable. A model may be designed to operate using text and structured information when an image is missing, or it may use a previously generated representation when the latest sensor value has not arrived. Such approaches can improve availability, but they also create the risk that model quality will vary substantially depending on which modalities are present, making monitoring and calibration essential.
Engineers therefore need to distinguish between different forms of missingness because the absence of a modality may itself contain information. A missing sensor could indicate a hardware problem, while a missing customer image may simply mean that the user did not upload one. Treating both conditions identically can cause the model or downstream decision layer to interpret incomplete data incorrectly. The pipeline should therefore preserve metadata describing why a modality is unavailable and whether its absence is expected, temporary, or anomalous.
Key Takeaway
Production-scale multimodal ML requires coordinated storage, compute, versioning, fallback, and monitoring strategies because failures can occur independently within each modality or within the relationships connecting them. Reliable systems preserve end-to-end lineage, support graceful operation when inputs are incomplete, and monitor both individual data streams and cross-modal alignment so that the model receives consistent context throughout its lifecycle.
Section 4: Why Multimodal Data Engineering Will Become a Core ML Skill
Multimodal Pipelines Will Become the Foundation of Context-Rich AI
The increasing adoption of multimodal AI is changing what modern machine-learning systems consider useful context because real-world events rarely exist in only one data format. A customer support interaction may include written messages, call recordings, screenshots, account activity, and product information, while an autonomous system may combine visual observations, spatial measurements, navigation signals, and machine telemetry. As models become more capable of reasoning across these inputs, the underlying data infrastructure must preserve the relationships that allow those modalities to describe the same event coherently.
This makes multimodal pipelines increasingly important as a foundation for context-rich AI because the model cannot recover relationships that the data pipeline has already destroyed. If an image is incorrectly associated with a text description, or a sensor observation is shifted relative to the corresponding video frame, the model may learn a relationship that appears statistically plausible but does not represent the actual environment. The quality of multimodal AI therefore depends heavily on engineering decisions that occur before model training, including synchronization, identity resolution, metadata preservation, preprocessing, and validation.
The role of the data pipeline also expands as models move from experimentation into real-time applications. A multimodal assistant may need to interpret a user's text and image together, while a robotics system may need to combine camera observations with rapidly changing sensor streams under strict latency constraints. The pipeline must therefore provide not only accurate data but also timely context, making freshness, scheduling, caching, and resource management part of the intelligence infrastructure.
Data Infrastructure and Model Architecture Will Become More Tightly Coupled
Traditional ML systems often maintain a relatively clear separation between data engineering and model development, with data pipelines producing features that models consume through standardized interfaces. Multimodal systems make that separation less rigid because model architecture can determine which forms of data must be retained, how they should be synchronized, which representations should be generated, and how long those representations should remain available. At the same time, the capabilities and limitations of the data infrastructure can influence which multimodal architectures are practical.
A model that requires raw video, high-resolution images, continuous audio, and real-time sensor streams imposes very different storage and compute requirements from a model that consumes precomputed embeddings. Engineers therefore need to make decisions jointly about the raw-data layer, representation layer, model architecture, and serving strategy. Precomputing an embedding can reduce inference latency but may introduce freshness problems, while generating representations on demand preserves current information at the cost of additional compute.
This coupling also affects model experimentation because researchers may want to test new fusion strategies, encoders, or context windows without rebuilding entire data pipelines. Reusable multimodal datasets, standardized metadata, versioned transformations, and representation registries can provide a stable foundation that allows model teams to experiment quickly while preserving data lineage. The infrastructure therefore becomes an abstraction layer between raw heterogeneous sources and rapidly evolving model architectures.
The broader data-centric perspective described in “Data-Centric AI: Why Improving Your Dataset Can Beat Changing Your Model” becomes particularly relevant because improving alignment, completeness, representation quality, and labeling can sometimes produce greater gains than replacing the model with a more complex architecture. Multimodal systems make this principle especially visible because the quality of the relationships among inputs can determine whether the model learns useful cross-modal associations or simply learns from noisy combinations of otherwise valid data.
Real-Time Multimodal Systems Will Introduce New Streaming Challenges
As multimodal AI moves into interactive and physical environments, pipelines will increasingly need to process multiple data streams simultaneously rather than assembling multimodal inputs from static datasets. A vehicle may generate camera frames, lidar observations, GPS information, and telemetry continuously, while an interactive application may combine audio, text, screen content, and user actions during an ongoing session. Each stream can have a different arrival rate, latency, storage format, and reliability profile, making real-time multimodal synchronization significantly more difficult than offline dataset construction.
Event-time processing becomes particularly important because modalities may arrive at different moments even when they describe the same underlying event. Network delays, buffering, sensor latency, and processing differences can cause an observation to reach the pipeline after other modalities have already been processed. Engineers need stateful processing and synchronization strategies that can temporarily hold information, reconcile late events, and determine when enough context exists to produce a reliable inference.
Latency budgets also need to be allocated across the entire pipeline because multimodal inference may require several encoders and preprocessing stages before the fusion model can execute. A system with a fast fusion layer can still violate application requirements if image decoding, audio processing, feature retrieval, or sensor synchronization consumes most of the available time. This means optimization must consider end-to-end latency rather than focusing only on model inference speed.
Streaming multimodal systems also create new failure modes because one modality may degrade while others remain healthy. A missing camera stream, delayed sensor, or corrupted audio segment can change the quality of the combined representation without necessarily causing the entire pipeline to fail. Engineers therefore need modality-aware fallback strategies, freshness thresholds, and uncertainty handling so that the system can distinguish between complete context and partial context when making real-time decisions.
Key Takeaway
Multimodal data engineering is becoming a core ML skill because modern AI systems increasingly depend on synchronized combinations of text, images, audio, video, structured data, and real-time signals. The future will require tightly integrated data and model infrastructure that can preserve cross-modal relationships, support streaming inference, manage heterogeneous representations, and maintain reliable lineage from raw inputs to production predictions, making data architecture a central part of multimodal AI engineering.
Conclusion
Multimodal machine learning is changing the role of data engineering because modern AI systems increasingly depend on information that exists across several different forms at the same time. Text, images, audio, video, structured records, sensor measurements, and behavioral events can each provide useful evidence, but the real value often comes from understanding how those observations relate to one another. This makes the data pipeline a critical part of the intelligence system because a model cannot recover relationships that have been lost through incorrect synchronization, incomplete metadata, inconsistent transformations, or poor data quality.
Traditional ML pipelines can often be organized around a relatively stable flow from structured data to engineered features and model inputs, while multimodal systems require multiple ingestion paths, modality-specific preprocessing, shared identifiers, temporal alignment, representation generation, and cross-modal validation. The engineering challenge therefore moves beyond simply collecting more data and toward preserving a coherent representation of the real-world event that the model is expected to understand.
Synchronization is one of the most important differences.
An image, audio segment, sensor observation, and textual description may all be valid individually while representing different moments or contexts when combined incorrectly. This can create training examples that appear technically correct while encoding false relationships, potentially causing the model to learn correlations that do not exist in the real environment. Event timestamps, processing delays, sampling frequencies, identifiers, spatial context, and late-arriving data therefore become part of the model's effective data specification.
Data quality also becomes multidimensional because each modality can fail independently.
An image may be corrupted, an audio stream may be incomplete, a sensor can become stale, or a structured source may change its schema while other inputs continue operating normally. Validating each source independently is therefore insufficient because the combined multimodal representation may still be inconsistent. Engineers need modality-specific checks as well as cross-modal validation that determines whether the inputs belong together and contain enough information for the intended prediction.
Frequently Asked Questions
1. What is a multimodal data pipeline?
A multimodal data pipeline is an ML data infrastructure system designed to collect, process, synchronize, transform, store, and serve multiple types of data, such as text, images, audio, video, sensor signals, and structured information, for machine-learning applications.
2. How is a multimodal pipeline different from a traditional ML pipeline?
A traditional ML pipeline may primarily process structured or single-modality data, while a multimodal pipeline must handle different formats, preprocessing requirements, sampling rates, storage systems, and temporal relationships while ensuring that inputs from different modalities remain correctly associated.
3. Why is synchronization important in multimodal machine learning?
Synchronization ensures that different observations refer to the same underlying event or context. Incorrect timestamps, delays, or associations can cause a model to receive technically valid inputs that describe different moments, leading it to learn or infer relationships that are not actually present.
4. What types of data can be included in a multimodal pipeline?
A multimodal system can combine text, images, audio, video, structured tables, sensor measurements, documents, behavioral events, location data, and other information sources, with the exact combination depending on the application and the model architecture.
5. How do engineers preprocess different modalities?
Each modality generally receives specialized preprocessing, such as tokenization for text, resizing and normalization for images, sampling and segmentation for audio, frame extraction for video, and schema or statistical validation for structured and sensor data, before the resulting representations are aligned for downstream processing.
6. What are multimodal embeddings?
Multimodal embeddings are numerical representations that capture information from different data types in forms that machine-learning models can compare or combine. They can be generated independently for each modality or learned jointly through multimodal architectures.
7. What is cross-modal alignment?
Cross-modal alignment is the process of ensuring that representations from different modalities correspond to the same underlying entity, event, time period, or context, allowing the model to learn meaningful relationships among otherwise different forms of information.
8. Do multimodal systems need a feature store?
Not necessarily, but they often require infrastructure that provides some of the capabilities associated with feature stores, including versioning, retrieval, freshness management, lineage, metadata, and reusable representations. Multimodal environments may additionally require object storage, vector databases, and streaming systems.
9. How do engineers handle missing modalities?
Engineers can design fallback strategies that allow the system to operate with partial inputs, use cached or previously generated representations, switch to specialized models, return lower-confidence predictions, or delay inference when the missing modality is essential to reliable decision-making.
10. Why is multimodal data quality difficult?
Each modality has its own failure modes, but the combined system also introduces cross-modal failures involving timestamp mismatches, incorrect associations, stale representations, incompatible versions, and incomplete context. Consequently, engineers need both modality-specific validation and relationship-level validation.
11. How does multimodal data affect storage requirements?
Multimodal applications can generate substantially larger datasets because images, audio, video, documents, embeddings, and sensor streams have different storage characteristics. Production architectures may therefore combine object storage, databases, vector infrastructure, and streaming systems instead of relying on a single storage technology.
12. How do engineers maintain reproducibility in multimodal ML?
Reproducibility requires versioning not only the model but also source data, preprocessing pipelines, modality-specific encoders, synchronization rules, representation-generation processes, dataset definitions, and filtering logic. The goal is to reconstruct the exact multimodal inputs that produced a particular training run or prediction.
13. What challenges arise when multimodal ML operates in real time?
Real-time multimodal systems must synchronize streams arriving at different rates, manage late events, maintain fresh representations, meet end-to-end latency requirements, and handle situations in which one modality becomes unavailable. These challenges make streaming infrastructure and state management important parts of the ML architecture.
14. Can multimodal models work when some inputs are unavailable?
They can when the model and data pipeline are explicitly designed for partial modality availability. Engineers can train or adapt models to handle missing inputs, but they need to evaluate how prediction quality changes under different modality combinations and communicate uncertainty when important context is absent.
15. Why will multimodal data engineering become increasingly important?
Modern AI systems are moving toward richer representations that combine multiple forms of information, making data quality, synchronization, storage, lineage, and real-time processing central to model performance. As multimodal models become more capable, the engineering infrastructure that prepares and connects their inputs will increasingly determine whether those capabilities can be deployed reliably at production scale.