Section 1: Understanding the Inference Optimization Problem
Training Performance Does Not Guarantee Efficient Inference
Machine-learning engineers often spend substantial effort optimizing training because training determines how quickly models can be developed, evaluated, and iterated. Production inference presents a different engineering problem because the model must repeatedly generate predictions under operational constraints involving latency, throughput, memory, infrastructure cost, and reliability. A model can train efficiently on powerful hardware and still become expensive or slow when millions of predictions must be generated continuously.
Training and inference also have fundamentally different computational patterns. Training requires forward passes, loss calculation, backpropagation, gradient updates, and repeated iterations across datasets, while inference generally requires only the forward computation needed to generate a prediction. However, inference may occur at significantly greater frequency, making small inefficiencies meaningful at production scale. An additional few milliseconds per request can translate into substantial infrastructure requirements when traffic is high, particularly when models are embedded inside interactive products.
This difference makes inference optimization more than a model-development exercise. Engineers need to understand the environment in which predictions are consumed and determine whether the primary objective is minimizing response time, maximizing requests per second, reducing memory consumption, lowering infrastructure cost, or maintaining predictable performance during traffic spikes. The correct optimization strategy depends on these requirements because an approach that improves throughput can sometimes increase individual request latency.
End-to-End Latency Matters More Than Model Execution Time
Inference latency is frequently discussed as though it represents only the time required to execute a model, but production prediction pipelines usually involve multiple stages. An incoming request may require input validation, feature retrieval, preprocessing, serialization, network communication, model execution, post-processing, and response delivery before the final prediction reaches the application. Optimizing the model while ignoring the rest of this pipeline can therefore produce limited improvement.
Engineers should begin by decomposing total latency into measurable components so that optimization targets the actual bottleneck. A model that takes 20 milliseconds to execute may appear slow until profiling shows that feature retrieval consumes 50 milliseconds and network communication consumes another 30 milliseconds. In that situation, reducing model execution from 20 to 15 milliseconds improves total response time by much less than optimizing the feature or network path.
The same principle applies to memory behavior because inference performance depends not only on arithmetic operations but also on how efficiently data moves through memory and between processing components. Large intermediate tensors, unnecessary copies, inefficient serialization, and repeated data transformations can create hidden overhead. The engineering challenge is therefore to optimize the complete critical path rather than focusing exclusively on the neural network or statistical model itself.
Profiling Must Come Before Optimization
Optimization without profiling can lead engineers toward improvements that look valuable in theory but have little measurable effect in production. The first task is therefore to establish a performance baseline using representative inputs, realistic request rates, target hardware, and production-like concurrency. Metrics should capture latency, throughput, memory utilization, processor utilization, and error behavior so teams can identify where resources are actually being consumed.
Latency should also be examined beyond averages because production workloads often produce uneven response times. Average inference time may remain low while a smaller percentage of requests experiences significant delays caused by resource contention, large inputs, queueing, cache misses, or external dependencies. Measuring tail latency provides a clearer view of whether the system can meet its service objectives consistently.
Profiling should occur at multiple levels because bottlenecks can exist inside the model, runtime, application, or infrastructure. Model-level profiling can reveal expensive operators and unnecessary computations, while system-level profiling can expose serialization overhead, data movement, network delays, CPU contention, or accelerator underutilization. A disciplined process separates measurement from optimization so engineers can determine whether each change actually improves the desired production metric.
This approach also reduces the risk of premature complexity. Introducing specialized runtimes, custom kernels, compression techniques, or additional caching layers can increase operational burden, so each intervention should be justified by measurable performance gains. The objective is not to optimize every component but to remove the constraints that materially affect the system's production behavior.
Optimization Requires a Quality-Latency Trade-Off Framework
Inference optimization becomes more challenging when model quality must remain within acceptable limits. Faster inference is valuable only when the resulting predictions remain sufficiently accurate for the application's objectives. Engineers therefore need explicit quality thresholds before applying techniques such as pruning, quantization, architectural simplification, or aggressive compression.
Quality should be evaluated using metrics relevant to the actual task rather than relying on a single aggregate score. A small change in overall accuracy may conceal a significant decline in performance for an important user segment, rare class, or high-risk prediction category. Optimization experiments should consequently compare latency and resource metrics with the same evaluation criteria used to judge model behavior in production.
The best optimization strategy is often not the technique that produces the largest theoretical speedup, but the technique that provides the strongest improvement within an acceptable quality budget. Engineers can establish multiple candidate configurations and evaluate their latency, throughput, memory footprint, infrastructure cost, and predictive performance together. This creates a measurable trade-off surface from which teams can select an operating point that fits the product's actual requirements.
The principle described in “Model Complexity vs Business Value: Finding the Right Level of ML” is especially relevant here because additional model complexity has value only when its predictive improvement justifies its computational and operational cost. Inference optimization applies the same discipline in reverse by asking how much computational complexity can be removed before the model's practical value begins to decline.
Key Takeaway
Inference optimization begins with measurement, not modification, because engineers need to understand where latency, memory consumption, and compute resources are actually being spent before selecting an optimization technique. The strongest results come from evaluating the complete serving path, profiling realistic production workloads, monitoring tail behavior, and defining an explicit quality budget so that improvements in inference speed remain aligned with the predictive performance and business value the model is expected to deliver.
Section 2: Model-Level Techniques for Faster Inference
Architectural Simplification Reduces Computation at the Source
One of the most effective ways to accelerate inference is to reduce the amount of computation the model needs to perform in the first place, because every additional layer, parameter, activation, and operation can contribute to execution time and memory consumption. Engineers can begin by examining whether the existing architecture contains unnecessary depth, excessive width, redundant layers, or computationally expensive operations whose contribution to predictive quality is relatively small. Simplifying the architecture can produce sustainable inference improvements because the reduction occurs directly within the computational graph rather than relying entirely on serving infrastructure to compensate for an inefficient model.
Architecture selection should also consider how the model will actually be executed because theoretical operation counts do not always translate directly into production latency. Two models with similar parameter counts can perform differently depending on operator support, memory access patterns, tensor dimensions, parallelization opportunities, and the capabilities of the target accelerator. An architecture that appears slightly larger on paper may therefore produce lower real-world latency when its operations are better optimized by the deployment runtime and hardware.
Engineers can further improve efficiency by selecting architectures designed around the target inference environment. Efficient convolutional blocks, reduced attention complexity, factorized operations, smaller embedding dimensions, and streamlined computational paths can lower execution cost without necessarily producing substantial quality degradation. The optimization objective is not simply to minimize parameter count, but to identify unnecessary computation while preserving the representations that contribute most strongly to the model's predictions.
Pruning Removes Computation With Limited Predictive Value
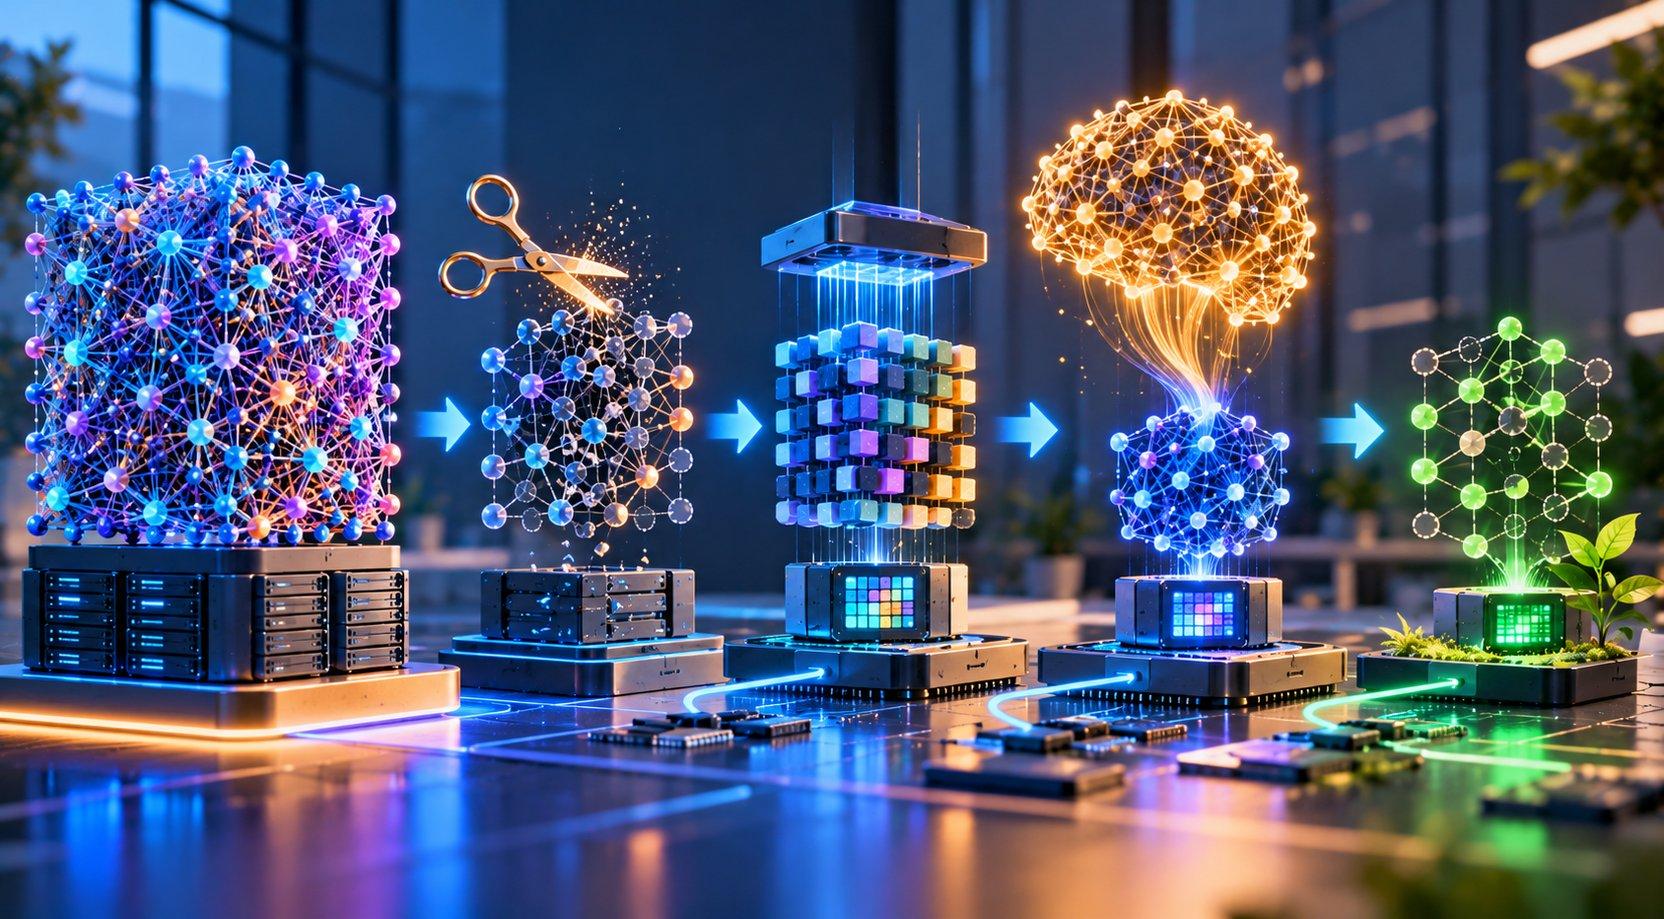
Pruning provides another way to reduce inference cost by removing parameters or structural components that contribute relatively little to the final prediction. The underlying idea is that trained models frequently contain redundancy, meaning that some weights, neurons, channels, filters, or even entire layers can be removed while maintaining acceptable predictive performance. By eliminating this excess capacity, engineers can potentially reduce model size, memory usage, and computational requirements.
Unstructured pruning removes individual weights according to criteria such as magnitude or learned importance, while structured pruning removes groups of parameters that correspond to hardware-relevant components such as channels, filters, attention heads, or blocks. Structured approaches can be especially useful for production inference because the resulting model architecture is easier for standard runtimes and accelerators to execute efficiently. A sparse model that theoretically contains fewer active parameters may deliver limited speedup when the underlying hardware does not exploit that sparsity effectively.
Pruning therefore requires a validation cycle in which engineers compare predictive quality, latency, memory consumption, and throughput before and after compression. Excessive pruning can remove information that becomes important for difficult or underrepresented inputs even when aggregate validation metrics appear stable. The most useful pruning strategy is consequently one that targets genuine redundancy while retaining the structures required for reliable performance across the production input distribution.
Quantization Reduces the Cost of Numerical Computation
Quantization improves inference efficiency by representing model weights and, in some cases, activations with lower numerical precision than the original training representation. Moving from higher-precision formats to FP16, BF16, INT8, or other supported formats can reduce memory footprint and accelerate arithmetic on compatible hardware. Lower precision can also reduce memory bandwidth requirements, which becomes important when data movement rather than raw computation limits performance.
The practical benefit of quantization depends heavily on model architecture and deployment hardware, so engineers should evaluate it using the actual serving stack rather than relying on theoretical reductions in storage or arithmetic cost. A runtime may support certain numerical formats particularly well while providing limited benefit for others, and some operations may remain dependent on higher precision. Quantization can therefore produce different latency improvements across processors, GPUs, inference accelerators, and edge devices.
Accuracy preservation is equally important because aggressive quantization can alter model behavior, particularly for sensitive layers or models with narrow numerical margins. Post-training quantization may be sufficient for some workloads, while quantization-aware training can provide better control when maintaining predictive quality is critical. Engineers should compare task-specific quality metrics against latency, throughput, and memory changes to identify an acceptable configuration.
The broader concepts in “Quantization Explained: How AI Models Become Faster and Cheaper to Run” demonstrate why numerical precision is both a modeling and infrastructure decision. The most effective implementation occurs when model developers understand the numerical requirements of the architecture and infrastructure engineers understand how those choices affect actual hardware execution.
Knowledge Distillation and Hybrid Optimization Preserve Important Capability
Knowledge distillation approaches inference optimization from another direction by transferring useful behavior from a larger teacher model into a smaller student model. Instead of attempting to remove computation from the original model alone, engineers train a more efficient architecture to reproduce the teacher's useful predictions, representations, or probability distributions. The resulting student model can often operate with substantially lower inference cost while retaining much of the teacher's practical capability.
Distillation becomes particularly valuable when the original model contains capacity that is useful during difficult cases but excessive for routine inputs. A carefully trained student can capture many of the teacher's decision boundaries while using fewer parameters and simpler operations during production inference. Engineers should nevertheless validate performance across important subgroups, difficult examples, and rare cases because compression can disproportionately affect inputs that are less common in the training or validation data.
The strongest inference improvements often combine multiple techniques rather than depending on one intervention. An engineer might simplify an architecture, apply structured pruning, reduce numerical precision, and then optimize the resulting computational graph for the target runtime. Each technique can contribute incremental gains while allowing the quality impact of every change to remain measurable and controlled.
This layered approach is particularly important because no single optimization method dominates across every workload. Some models benefit primarily from quantization, others from architectural redesign or distillation, and some gain more from eliminating unnecessary computation around the model. The correct objective is therefore to build the most efficient model configuration that satisfies the application's quality, latency, memory, and cost requirements simultaneously.
Key Takeaway
Model-level inference optimization works best when engineers reduce unnecessary computation systematically through architectural simplification, structured pruning, quantization, and knowledge distillation while continuously validating predictive quality. The goal is not to produce the smallest model possible, but to identify the most efficient model configuration that delivers the required accuracy and robustness with substantially lower computational cost and predictable production inference performance.
Section 3: Runtime and Serving Optimization
Inference Runtimes Translate Model Graphs Into Faster Execution
Optimizing the model itself is only part of the inference problem because the same computational graph can behave very differently depending on the runtime responsible for executing it. Production inference runtimes can analyze the model graph, optimize execution order, select efficient kernels, eliminate redundant operations, and map supported operators to hardware-specific implementations. These transformations can reduce execution overhead without changing the model's learned parameters or requiring additional training.
Graph-level optimization is particularly valuable when the original model contains operations that can be combined or simplified during execution. Operator fusion can merge consecutive operations into a single kernel, reducing intermediate memory transfers and the overhead associated with launching multiple operations. Constant folding can evaluate expressions that do not change between requests ahead of time, while optimized memory planning can reduce unnecessary allocation and copying during inference.
Compilation can provide additional performance improvements by generating execution plans tailored to the model and target hardware. Rather than interpreting every operation independently at runtime, compiled execution can optimize the computational graph as a whole and make better decisions about memory access, parallelism, and operator selection. However, compilation benefits depend on operator coverage and workload characteristics, so engineers should benchmark the compiled model using production-like requests rather than assuming that every model will receive the same improvement.
Batching and Concurrency Increase Hardware Utilization
Inference workloads often leave hardware underutilized when requests are processed individually, particularly on accelerators designed to perform large numbers of operations in parallel. Batching allows multiple requests to be processed together, increasing computational utilization and potentially improving throughput. This can be especially effective for workloads where individual requests have similar shapes and can share the same execution path.
The challenge is that batching introduces a waiting period because the serving system may need to collect multiple requests before starting inference. That additional queueing time can conflict directly with strict latency requirements. Engineers therefore need to determine whether the application is primarily throughput-sensitive or response-time-sensitive and select an appropriate batching strategy accordingly. Static batching may work well for predictable workloads, while dynamic batching can adjust batch formation according to incoming traffic and configured latency limits.
Concurrency creates another optimization opportunity because multiple requests can be processed simultaneously when sufficient compute and memory resources are available. Yet excessive concurrency can cause contention, cache pressure, memory exhaustion, and longer queueing delays. A serving configuration that maximizes utilization at low traffic can therefore produce poor tail latency when the system approaches capacity. Benchmarking should include realistic concurrency levels, request distributions, and traffic bursts so optimization decisions reflect actual operating conditions.
Memory Management and Caching Can Remove Hidden Inference Costs
Inference performance is influenced heavily by memory movement because transferring large tensors can become more expensive than performing the arithmetic required to process them. Engineers can improve performance by reducing unnecessary allocations, reusing memory buffers, controlling intermediate tensor lifetimes, and minimizing transfers between host memory and accelerators. These changes become increasingly important for large models where memory bandwidth and capacity can constrain performance even when computational throughput remains available.
Caching can eliminate repeated inference work when requests produce identical or sufficiently stable outputs. Predictions, embeddings, feature transformations, and intermediate representations can all be candidates for caching depending on how frequently they are reused and how quickly the underlying information changes. The effectiveness of caching depends on the workload's locality because a cache provides meaningful benefits only when requests contain patterns that can be reused.
Cache design must also account for correctness because stale results can be more damaging than slow results in systems where predictions depend on rapidly changing data. Engineers need appropriate expiration, invalidation, and versioning mechanisms so cached outputs remain consistent with current models and features. The broader principles discussed in “Caching for AI Applications: The Overlooked Technique for Reducing Inference Costs” demonstrate why avoiding unnecessary computation can sometimes deliver greater production gains than accelerating computation that still has to occur.
Key Takeaway
Runtime and serving optimization can produce substantial inference improvements without modifying the underlying model by improving graph execution, batching, concurrency, memory management, caching, scheduling, and workload isolation. The most effective approach evaluates these mechanisms together under realistic traffic and hardware conditions, ensuring that higher throughput and better resource utilization do not come at the expense of the predictable latency and reliability required by production ML systems.
Section 4: Hardware-Aware Inference and the Future of Optimization
Hardware Selection Should Influence Model Design
Inference optimization becomes significantly more effective when model architecture and deployment hardware are considered together rather than treated as independent decisions. CPUs, GPUs, neural processing units, and specialized inference accelerators differ in their supported numerical formats, memory bandwidth, parallel execution capabilities, and optimized operators, meaning that a model designed without considering its execution environment may fail to achieve its theoretical performance in production. Engineers therefore need to evaluate the target hardware early enough in the development lifecycle to influence architectural and numerical decisions before deployment constraints become difficult to change.
Hardware-aware design involves understanding which operations execute efficiently on the intended platform and which operations create bottlenecks. A computational graph containing unsupported or poorly optimized operators may force execution through slower implementations or require costly transfers between processing components. Similarly, a model that is computationally compact but generates large intermediate tensors can become memory-bandwidth bound rather than compute bound. The strongest optimization decisions therefore consider parameter size, operator compatibility, memory movement, precision support, and parallelization opportunities together.
The same principle applies to infrastructure selection because maximizing raw accelerator performance is not always equivalent to minimizing end-to-end inference cost. A high-end accelerator may provide excellent throughput while being economically inefficient for low-volume workloads, whereas a CPU-optimized model may deliver better overall economics for lightweight requests. Engineers need to optimize against the actual production objective, which may include latency, throughput, utilization, energy consumption, or cost per prediction rather than benchmark speed alone.
Edge Inference Creates New Optimization Constraints
Moving inference closer to users, devices, or data sources can significantly reduce network overhead and improve responsiveness, but edge environments introduce constraints that rarely exist in centralized infrastructure. Mobile devices, embedded systems, industrial hardware, and edge servers may have substantially less memory, compute capacity, power availability, and thermal headroom than cloud accelerators. Models therefore need to be optimized not only for fast execution but also for predictable resource consumption under constrained conditions.
Quantization, pruning, distillation, and compact architectures become particularly valuable in these environments because reducing model size can improve both memory efficiency and execution performance. Smaller models can also reduce transfer and storage requirements when models need to be distributed across large numbers of devices. However, edge deployment creates additional operational challenges because hardware configurations can vary significantly, making compatibility and benchmarking more complicated.
Hybrid architectures can address some of these limitations by distributing computation between edge and cloud environments. An edge model can perform an initial prediction or filtering step, while more computationally intensive processing is delegated to a centralized service when connectivity and latency budgets permit. This approach can reduce unnecessary cloud inference while preserving access to larger models for difficult cases, creating a flexible architecture that balances responsiveness, accuracy, and infrastructure cost.
Inference Optimization Will Become a Continuous Engineering Discipline
Inference performance cannot remain a one-time optimization completed immediately before deployment because models, workloads, hardware, and application requirements continually change. A model may receive new training data, gain additional capabilities, encounter larger inputs, or serve substantially more traffic over time, causing inference characteristics to shift even when its architecture remains unchanged. Continuous profiling and performance regression testing are therefore becoming increasingly important for production ML teams.
Modern ML platforms can help operationalize this process by tracking latency, throughput, resource utilization, model version, hardware configuration, and quality metrics together. Performance changes can then be evaluated alongside model releases rather than discovered only after users experience degraded responsiveness. Automated benchmarking can compare candidate models and runtime configurations before deployment, while staged rollouts can verify that an optimization behaves as expected under real production traffic.
This continuous approach also enables teams to optimize for changing business requirements. A system initially designed around latency may later face infrastructure-cost constraints as traffic grows, while an edge application may prioritize energy consumption as deployments scale. The best optimization strategy can therefore change over the lifetime of the product, making inference efficiency an ongoing engineering concern rather than a fixed technical specification.
As ML workloads become more computationally intensive and inference becomes embedded in increasingly interactive products, this discipline will become central to ML platform engineering. The principles behind “Efficient ML: How to Build High-Performance Models With Less Compute” reinforce this direction by emphasizing that performance should be designed systematically across models, infrastructure, and resource constraints rather than achieved through isolated optimizations.
Key Takeaway
Hardware-aware model design, edge deployment, adaptive inference, and continuous performance engineering will increasingly define how efficient ML systems are built and operated. Engineers can achieve better inference efficiency by aligning architectures with hardware capabilities, distributing computation intelligently, adapting compute to request complexity, and continuously measuring performance after deployment, ensuring that latency and resource improvements remain sustainable as models, workloads, and production environments evolve.
Conclusion
Inference optimization is one of the most important engineering disciplines for taking machine-learning models from successful experiments to reliable production systems. A model can deliver excellent predictive quality while still creating unacceptable latency, infrastructure costs, memory pressure, or scalability challenges when it serves real production traffic. For ML engineers, the objective is therefore not simply to make inference faster, but to identify the most efficient operating point where model quality, latency, throughput, resource utilization, and cost remain aligned with the application's requirements.
The optimization process should begin with profiling because performance problems are often located outside the model itself. Feature retrieval, preprocessing, serialization, network communication, memory transfers, queueing, and runtime scheduling can all contribute to end-to-end latency. Once the bottleneck is understood, engineers can apply targeted techniques such as architectural simplification, structured pruning, quantization, knowledge distillation, graph optimization, operator fusion, batching, caching, and concurrency control. Each technique should be evaluated against production-oriented metrics rather than theoretical improvements alone.
Model-level optimization remains particularly valuable because removing unnecessary computation can reduce costs across every future prediction. However, aggressive compression is useful only when predictive quality remains within an acceptable range. Quantization can accelerate execution on compatible hardware, pruning can remove redundant structures, and distillation can transfer important capabilities into smaller models, but each approach requires careful validation against task-specific quality metrics and important edge cases.
Runtime and serving optimization extend these improvements beyond the model. Optimized inference runtimes can transform computational graphs, while batching and concurrency can improve hardware utilization when their queueing costs remain within the latency budget. Efficient memory management and caching can eliminate repeated work, and workload isolation, request scheduling, and autoscaling can help preserve predictable performance when traffic changes.
The future of inference optimization will increasingly depend on hardware-aware design and adaptive execution. Models will be designed with target accelerators in mind, edge devices will run increasingly capable compact models, and inference systems will dynamically allocate computational resources according to request complexity and available capacity. This shift will make inference optimization a continuous engineering discipline rather than a one-time activity performed before production deployment.
Ultimately, the strongest inference optimization strategy is the one that removes unnecessary computation without removing the capabilities that create business and user value. ML engineers who treat model quality, latency, throughput, hardware efficiency, and operational cost as interconnected constraints can build production systems that remain fast, scalable, reliable, and economically sustainable as workloads evolve.
Frequently Asked Questions
1. What is inference optimization in machine learning?
Inference optimization is the process of improving how efficiently a trained machine-learning model generates predictions in production. The objective can include reducing latency, increasing throughput, lowering memory consumption, reducing infrastructure costs, or improving hardware utilization while keeping predictive quality within an acceptable range.
2. Why is inference optimization important for ML engineers?
Inference occurs repeatedly after a model reaches production, often at volumes far greater than the number of training runs performed during development. Small inefficiencies in prediction time or resource consumption can therefore become significant infrastructure and user-experience problems when multiplied across large production workloads.
3. What is the difference between training optimization and inference optimization?
Training optimization focuses primarily on reducing the time and resources required to learn model parameters, whereas inference optimization focuses on making prediction execution efficient after the model has been trained. The two workloads have different computational characteristics, so a model that trains efficiently does not necessarily provide efficient production inference.
4. How should ML engineers begin optimizing inference?
Engineers should begin by establishing a production-like performance baseline and profiling the complete inference path. Measuring model execution, preprocessing, feature retrieval, network communication, memory usage, throughput, and tail latency helps identify the actual bottleneck before optimization techniques are introduced.
5. Can a smaller model always provide faster inference?
No, model size alone does not determine inference performance. Operator support, memory access patterns, tensor dimensions, runtime optimizations, hardware capabilities, and data movement can cause a smaller model to perform worse than a somewhat larger model that is better matched to the target execution environment.
6. How does pruning improve inference performance?
Pruning removes parameters or structures that contribute relatively little to model predictions, potentially reducing computation and memory requirements. Structured pruning can be particularly useful for production inference because removing complete channels, filters, heads, or blocks can be easier for standard runtimes and hardware to exploit than removing individual weights.
7. How does quantization reduce inference latency?
Quantization represents model parameters and, in some cases, activations using lower numerical precision. This can reduce memory bandwidth requirements and accelerate arithmetic on compatible hardware, although the actual performance improvement depends on the model, runtime, hardware platform, and numerical formats supported by the execution environment.
8. Can quantization reduce model quality?
Yes, aggressive quantization can alter model behavior and reduce predictive quality, particularly for numerically sensitive models or operations. Engineers can evaluate post-training quantization or use quantization-aware training when tighter control over quality degradation is required.
9. What is knowledge distillation, and why is it useful for inference?
Knowledge distillation trains a smaller student model to reproduce useful behavior from a larger teacher model. The resulting model can require fewer computational resources during inference while retaining much of the predictive capability of the larger model, making distillation particularly useful when serving efficiency is more important than preserving the original architecture.
10. How do inference runtimes accelerate machine-learning models?
Inference runtimes can optimize computational graphs, fuse compatible operations, eliminate redundant computation, select optimized kernels, and manage memory more efficiently. These transformations can improve execution speed without requiring engineers to retrain the underlying model.
11. Does batching always make inference faster?
Batching often improves throughput and hardware utilization, especially on highly parallel accelerators, but it can increase individual request latency because requests may need to wait for a batch to form. For latency-sensitive applications, engineers need to balance batch size and batching windows against the application's response-time requirements.
12. How does caching help optimize ML inference?
Caching can prevent repeated computation by reusing predictions, embeddings, feature transformations, or other intermediate results that remain valid across multiple requests. The effectiveness of caching depends on workload reuse patterns and requires appropriate expiration and invalidation mechanisms so that stale results do not compromise prediction quality.
13. Why is hardware-aware optimization important?
Different processors and accelerators support different numerical formats, operators, memory architectures, and parallel execution strategies. Designing and benchmarking models against the actual production hardware can therefore reveal optimization opportunities that are invisible when performance is evaluated only through abstract model characteristics.
14. What is adaptive inference?
Adaptive inference dynamically changes the amount or type of computation performed for a request according to factors such as input complexity, model confidence, request priority, or available system capacity. Lightweight paths can process routine requests, while more computationally expensive models or processing stages can be reserved for difficult cases.
15. How can ML teams prevent inference performance from degrading over time?
Inference performance should be monitored continuously alongside model quality, throughput, memory consumption, hardware utilization, and latency percentiles. Regression testing, production profiling, staged deployments, and consistent benchmarking can help teams identify performance degradation caused by model changes, new workloads, increased traffic, or infrastructure changes before those issues materially affect users.