Section 1: Why Production ML Systems Need Dynamic Model Routing
A Single Model Does Not Fit Every Production Request
Production machine-learning workloads rarely contain requests with identical characteristics, even when they originate from the same application. Inputs can differ in complexity, data quality, confidence, business importance, freshness requirements, and tolerance for latency, which means a model that performs well for one class of requests may be unnecessarily expensive or insufficient for another. Using a single model for every prediction can therefore force the system to apply the same computational cost and capability level regardless of what the request actually requires.
A lightweight model may be highly effective for common and predictable inputs because it can produce sufficiently accurate results with minimal inference cost. More ambiguous inputs, however, may require a larger model with greater representational capacity, additional features, or specialized training. When every request is sent to the largest available model, the system may achieve strong aggregate quality but consume significantly more compute than necessary. Conversely, using only the smallest model may improve latency and infrastructure efficiency while creating unacceptable quality degradation on difficult cases.
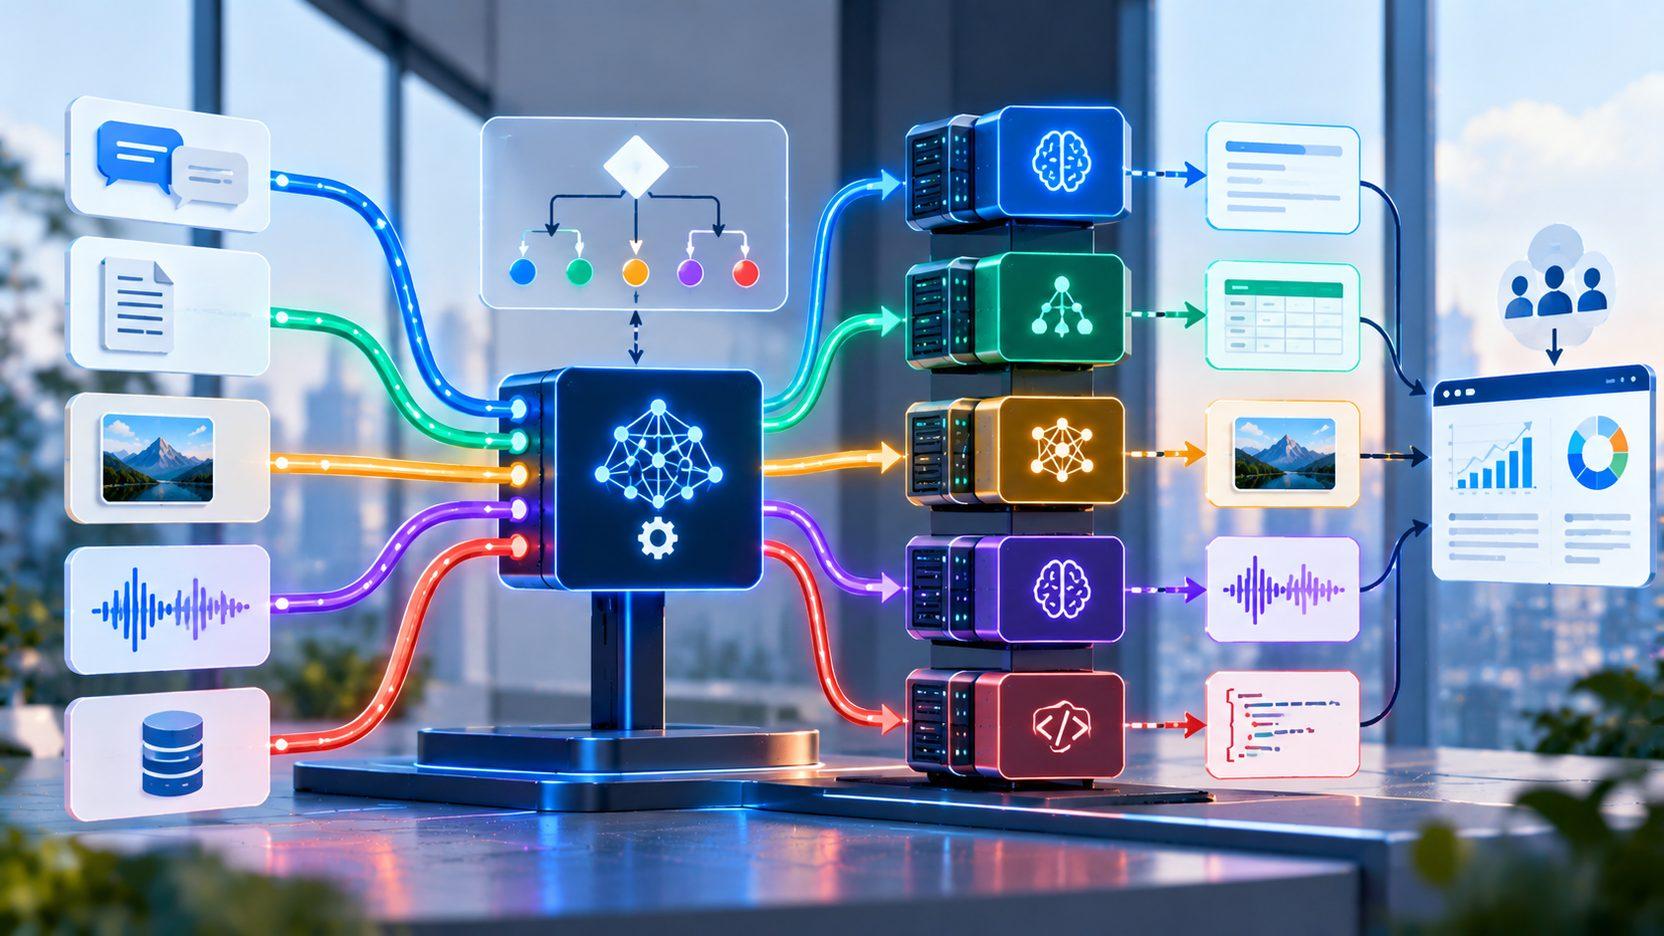
Dynamic model routing provides a way to allocate computational capability according to the characteristics of each request. Instead of treating model selection as a deployment-time decision, the production system evaluates incoming requests and determines which model is most appropriate for the current situation. This creates a flexible architecture in which different models contribute according to their strengths rather than competing to replace one another.
Latency, Accuracy, and Cost Create Competing Objectives
Model selection in production is rarely based on accuracy alone because engineering teams must balance several competing objectives simultaneously. A high-capacity model may deliver better predictions but require more memory, greater compute, and longer inference time, while a compact model may provide faster responses and lower operating costs with a modest reduction in predictive performance. The appropriate choice therefore depends on the requirements of the application and the characteristics of the request.
Latency-sensitive applications illustrate this trade-off particularly clearly. An interactive recommendation or fraud-detection service may have only a limited time window for generating a prediction, making a large model unsuitable for every request. A system can instead route straightforward requests to a faster model and reserve higher-capacity models for cases where additional computation is justified. This approach allows the production architecture to preserve access to stronger models without imposing their full cost on the entire workload.
Cost introduces another dimension because infrastructure resources are not unlimited. Running multiple large models continuously can increase accelerator usage and operational expenditure even when many requests could be handled effectively by simpler alternatives. Intelligent routing allows teams to treat computational capacity as a resource that can be allocated selectively, creating opportunities to optimize cost without reducing the quality available for important or difficult cases.
These trade-offs connect with the principles in “Model Complexity vs Business Value: Finding the Right Level of ML,” because model complexity should be justified by the value it creates. Model routing extends this idea by allowing complexity to vary at the request level rather than forcing the entire production workload to operate at the same level.
Request Diversity Creates an Opportunity for Specialized Models
Different models can be trained or optimized for different portions of the problem space, allowing routing systems to exploit specialization. One model may be optimized for high-volume routine inputs, another may focus on rare or difficult cases, and a third may target a particular customer segment, language, device type, or domain. Rather than selecting one universal model, the routing layer can direct each request toward the model whose strengths best match the request's characteristics.
Specialization can also improve engineering flexibility because individual models can evolve independently when their responsibilities are clearly defined. A team can optimize a low-latency model for common traffic while separately improving a high-capacity model for difficult predictions. New specialized models can then be introduced without requiring the entire production system to migrate immediately.
However, specialization creates a governance challenge because the routing system must understand when each model should be trusted. A model optimized for one segment may perform poorly outside its intended distribution, while a specialized model may introduce quality gaps if the router sends it requests that do not match its training characteristics. Routing decisions therefore need to incorporate model capabilities, input characteristics, and observed production behavior rather than relying solely on static assumptions.
Key Takeaway
Production ML systems benefit from dynamic model routing because different requests rarely require identical levels of model capacity, latency, or computational investment. By selecting models according to request characteristics, business priorities, quality requirements, and system conditions, engineers can avoid forcing every prediction through the most expensive model while still preserving higher-capacity models for cases where they provide meaningful additional value, turning model selection into an adaptive production capability rather than a fixed deployment decision.
Section 2: How Production Systems Decide Which Model Should Handle a Request
Input Characteristics Provide the First Routing Signals
A production routing system needs observable signals that help determine which model is appropriate for each request, and the most direct signals usually come from the input itself. Characteristics such as input size, language, data type, feature availability, historical behavior, request context, and estimated complexity can indicate whether a lightweight general-purpose model is sufficient or whether a specialized model should receive the request. The router can use these signals before inference begins, allowing computational resources to be allocated according to the requirements of the individual prediction rather than applying the same execution path to every input.
Feature-based routing can be particularly effective when different models have clearly defined areas of specialization. A vision system may route low-resolution images through an efficient model while sending complex images requiring finer detail to a higher-capacity architecture, while a recommendation system may select different models according to user history or inventory conditions. The routing decision can remain relatively inexpensive when it relies on metadata or lightweight preprocessing rather than executing every candidate model before choosing one.
Input complexity can also be estimated through a preliminary classifier or scoring mechanism when the relevant characteristics are not directly available. A small routing model can learn to distinguish routine cases from inputs that are ambiguous, unusual, or likely to benefit from additional model capacity. The router then becomes a predictive component itself, meaning it must be evaluated not only for decision speed but also for the downstream quality of the model selections it produces.
The central engineering requirement is that routing signals must be available quickly and remain stable enough to support reliable decisions. Expensive feature retrieval or complicated preprocessing can undermine the benefits of dynamic routing when the routing layer becomes slower than the inference savings it is designed to create.
Confidence and Expected Quality Can Trigger Model Escalation
Model confidence provides another important signal because a routing architecture can use an initial prediction to determine whether additional computation is necessary. A lightweight model can process the majority of requests, and cases where its confidence falls below a defined threshold can be escalated to a larger or more specialized model. This creates a model cascade in which computational capacity increases only when the initial prediction indicates that additional analysis may provide meaningful value.
Confidence-based routing requires careful calibration because raw confidence scores do not necessarily represent actual prediction reliability. A model may produce highly confident predictions for inputs that differ significantly from the training distribution, making confidence alone insufficient for determining whether a request should be escalated. Engineers can therefore combine confidence with uncertainty estimates, input characteristics, historical error patterns, or distribution-shift indicators to make routing decisions more robust.
The escalation threshold should also reflect business consequences because not every uncertain prediction requires the same treatment. A recommendation system may tolerate a small amount of uncertainty for low-impact interactions, while a fraud-detection system may justify additional computation when the financial or security consequences of an incorrect decision are significant. Routing policy should consequently be tied to the operational cost of errors rather than treating every confidence threshold as a purely technical parameter.
Latency, Cost, and Infrastructure Conditions Can Change the Decision
A routing decision does not always depend solely on the characteristics of the input because production systems also operate under changing infrastructure conditions. A large model may be the preferred choice under light traffic, but routing the same request to that model may become undesirable when accelerator capacity is constrained, queues are growing, or the latency budget is nearly exhausted. A production router can therefore incorporate real-time system signals when selecting among available models.
Latency-aware routing can prioritize models according to the amount of time available for the current request. When a request has a strict response deadline, the router may select a faster model even when a slower model could provide marginally better predictive quality. For asynchronous workloads with more generous response windows, the routing policy can favor higher-capacity models when their additional quality justifies the computational expense.
Cost-aware routing introduces another dimension by considering the computational price of each model. A high-capacity model may offer incremental quality improvements while consuming significantly more accelerator time, memory, or energy. The routing system can therefore define policies that reserve expensive models for requests where the expected quality improvement is sufficiently valuable, allowing routine traffic to be served through lower-cost alternatives.
Infrastructure-aware decisions become particularly important when multiple models share limited serving resources. Routing can distribute requests across replicas, model variants, or hardware classes to prevent localized overload and maintain predictable service. This transforms routing into a continuous resource-allocation mechanism in which model selection reflects not only what the request needs but also what the production environment can efficiently provide at that moment.
Key Takeaway
Production model routing can use input characteristics, confidence, expected quality, latency requirements, infrastructure conditions, and computational cost to determine which model should handle each request. Rule-based routers provide transparency and control, while learned routers can optimize increasingly complex decisions, but both approaches require continuous monitoring because the value of a routing decision depends on how accurately it matches request needs, model capabilities, production conditions, and the consequences of prediction errors.
Section 3: Designing Reliable Multi-Model Routing Architectures
Model Cascades Reduce Unnecessary Use of Expensive Models
A multi-model routing architecture becomes especially effective when models are organized into a cascade rather than treated as independent alternatives, because the system can progressively increase computational effort only when the earlier prediction does not satisfy the required confidence or quality threshold. A lightweight first-stage model can process common requests quickly, while a second model can handle uncertain cases, and a highly capable model can remain available for the smallest and most difficult portion of traffic. This structure allows the system to preserve high-end predictive capability without forcing every request through the most expensive inference path.
The success of a cascade depends on how accurately each stage identifies whether escalation is necessary. A first-stage model that is overly conservative may escalate too many requests and eliminate the expected cost and latency benefits, while an overly aggressive model may retain difficult cases that require additional computation. Engineers therefore need to evaluate not only the accuracy of individual models but also the accuracy of the escalation policy and the percentage of requests ultimately reaching each stage.
Cascades can also be designed around specialization rather than only model size. Different stages may represent models trained for different segments, languages, environments, or task characteristics, allowing the router to select a model based on suitability rather than capacity alone.
Fallback Models Protect Availability and Latency
Dynamic routing introduces additional dependencies because a request may rely on the availability of several possible models and their associated infrastructure. A preferred model may become overloaded, unavailable, slow to initialize, or temporarily incompatible with a particular input, so production systems need fallback paths that can preserve service when the primary route fails. A fallback model does not necessarily need to match the preferred model's quality exactly, because its primary purpose may be to maintain acceptable functionality when the optimal execution path is unavailable.
Fallback logic should account for both technical failure and latency risk. A request waiting for an overloaded high-capacity model may violate its response-time objective even when that model eventually produces a high-quality prediction. The routing layer can therefore use deadlines and timeout thresholds to redirect requests toward faster alternatives before the original path consumes the entire latency budget.
Graceful degradation becomes particularly important when model routing is part of a larger distributed system containing feature stores, inference servers, network services, and external dependencies. A failure in one component should not automatically result in a complete application failure when a lower-capability route can provide a useful response. The principles discussed in “Failure Modes of Modern AI Systems and How Engineers Prevent Them” are particularly relevant because reliable routing requires teams to anticipate failure modes rather than assuming that every model and dependency will remain healthy.
Load Balancing and Version Management Keep Routing Stable
Multi-model serving introduces resource-allocation challenges because several models may compete for limited CPU, GPU, memory, or accelerator capacity. A routing layer that selects models intelligently can still create performance problems if it directs too much traffic toward one model or hardware pool. Load balancing therefore needs to consider both request suitability and current resource utilization so that routing decisions do not create avoidable hotspots.
Traffic distribution can also change rapidly when a new model is introduced or when request characteristics shift. Engineers need controlled rollout mechanisms that allow a small percentage of traffic to reach a new model before expanding deployment. Shadow evaluation, canary traffic, and gradual routing adjustments can help teams compare quality and latency without immediately exposing the entire production workload to an unvalidated routing configuration.
Version management becomes more complex when multiple models coexist because each model can have different feature requirements, preprocessing logic, compatibility constraints, and performance characteristics. The routing system needs to understand which model versions are active, which inputs they support, and which feature or schema versions they expect. This is especially important when one model is updated while others remain unchanged, because inconsistent feature assumptions can create failures that are difficult to distinguish from routing errors.
Strong model governance therefore requires the router to treat model metadata as part of the production contract. The routing layer should understand model capabilities, supported inputs, expected latency, resource requirements, and quality characteristics so that requests are directed only toward compatible and operationally suitable candidates.
Key Takeaway
Reliable multi-model routing requires more than selecting the right model because the system must also manage escalation, fallback behavior, resource allocation, model versions, and production observability. Cascades can reduce unnecessary computation, fallback paths can preserve availability, load balancing can prevent resource hotspots, and detailed monitoring can reveal whether routing decisions actually improve quality, latency, and cost, allowing the routing layer to remain dependable as models and workloads change.
Section 4: The Future of Intelligent and Adaptive Model Routing
Learned Routers Will Make Model Selection More Context-Aware
Production model routing is likely to evolve from manually defined decision rules toward learned routing systems that can evaluate a request and estimate which available model is most likely to produce the best overall outcome. Instead of relying only on fixed thresholds, a learned router can consider multiple contextual signals simultaneously, including input characteristics, historical model performance, estimated inference cost, current latency, request priority, and infrastructure availability. This allows the routing layer to optimize for a broader objective than simply identifying the model with the highest offline accuracy.
A learned router can be trained using historical production outcomes in which each request is associated with the models that were available, their predictions, their execution costs, and the resulting quality. The router can then learn patterns that are difficult to capture through manually maintained rules, particularly when the relationship between request characteristics and model performance becomes complex. For example, two inputs that appear similar according to basic metadata may behave very differently across candidate models, and historical routing outcomes can reveal these differences.
The challenge is that the router itself becomes an ML component that requires training, validation, monitoring, and version management. Changes in the underlying models can invalidate routing assumptions, while changes in user behavior or data distributions can cause historical relationships to become less reliable. Production systems therefore need continuous evaluation of both the models being routed and the mechanism responsible for selecting them.
Cost-Aware Routing Will Optimize More Than Prediction Quality
As organizations deploy increasingly diverse model portfolios, the cost of inference will become an explicit factor in routing decisions. Different models can have substantially different requirements for compute, memory, accelerator time, and energy, while their quality improvements may vary depending on the request. A routing system that considers only predictive performance can therefore consume resources inefficiently by selecting expensive models even when a cheaper alternative would produce an equally useful result.
Cost-aware routing introduces an optimization problem in which the system evaluates the expected value of additional model capacity against its computational cost. A high-value request may justify an expensive model when a small improvement in quality has significant business consequences, while a routine request may be better served by a compact model whose performance is sufficient for the task. The routing layer can use predefined cost thresholds, quality targets, or more sophisticated utility functions to make these decisions.
This approach can become especially important as model serving moves toward portfolios containing specialized models with different latency and infrastructure characteristics. Rather than operating every model continuously at maximum capacity, systems can dynamically allocate requests across the portfolio according to expected demand and value. The broader principles in “The Economics of Machine Learning: Measuring the True Cost of a Model” become directly relevant because production model selection increasingly needs to account for the full economic cost of generating predictions.
Contextual Routing Will Adapt to Changing System Conditions
Future routing systems will increasingly incorporate real-time context because the best model for a request can change according to conditions that have nothing to do with the input itself. Hardware utilization, queue depth, traffic volume, geographic location, device capabilities, network conditions, and available latency can all influence which model provides the best practical outcome at a particular moment. A routing policy that remains static while these conditions change can therefore become inefficient even when its original design was sound.
Context-aware routing can respond dynamically to these conditions by shifting traffic between model variants, hardware pools, or inference paths. During periods of high accelerator utilization, the system may route more requests toward compact models, while quieter periods may allow greater use of high-capacity models. Similarly, edge devices with limited compute may use smaller local models while more capable infrastructure can support larger alternatives.
This creates a feedback loop between routing decisions and system state because routing changes workload distribution, while workload distribution changes the conditions that influence subsequent routing decisions. Engineers therefore need safeguards against unstable feedback patterns in which the router repeatedly redirects traffic in response to short-lived changes and creates oscillating load or unpredictable latency.
Key Takeaway
The future of ML model routing will be shaped by learned selection, cost-aware decision-making, contextual adaptation, and shared platform capabilities that continuously evaluate which model is most appropriate for each request. As production environments become more heterogeneous, intelligent routing will allow teams to distribute computation according to request complexity, model capability, system conditions, and business value, turning multi-model inference into an adaptive optimization layer rather than a static collection of deployed models.
Conclusion
ML model routing is becoming an important production engineering pattern as organizations move beyond single-model architectures and operate portfolios of models with different capabilities, costs, latency characteristics, and areas of specialization. A single model can provide a useful baseline, but it may not represent the most efficient choice for every request. Some inputs require greater predictive capacity, while others can be handled effectively by lightweight models, making dynamic selection a practical way to align computational effort with actual request requirements.
The strongest routing systems treat model selection as a multi-objective decision rather than a simple accuracy comparison. Input characteristics, confidence, expected quality, latency requirements, infrastructure availability, computational cost, and business importance can all influence the appropriate route. This allows production systems to reserve expensive models for requests where their additional capability creates meaningful value while handling routine traffic through faster and more economical alternatives.
Reliable routing also requires more than an intelligent selection mechanism because multiple models introduce additional operational complexity. Cascades need carefully designed escalation thresholds, fallback models need to preserve service when preferred routes become unavailable, and load balancing needs to prevent individual models or hardware pools from becoming overloaded. Model versioning and compatibility checks are equally important because different models can require different features, preprocessing logic, hardware resources, and input formats.
Observability is therefore a foundational component of model routing. Teams need visibility into how traffic is distributed, why particular models are selected, how each route performs, and whether the routing policy actually improves the desired combination of quality, latency, reliability, and cost. Monitoring should also examine model performance across relevant segments because an apparently successful routing strategy can still create hidden quality problems for specific populations or input categories.
The future of model routing will become increasingly adaptive as routing systems incorporate learned decision policies, real-time infrastructure conditions, cost constraints, and changing data distributions. Shared ML platforms will increasingly provide routing as a standard serving capability, allowing organizations to manage model portfolios through common mechanisms for traffic allocation, experimentation, governance, observability, and automated optimization.
Ultimately, the most effective production architecture will not necessarily be the one with the single strongest model. It will be the architecture that combines multiple models intelligently and directs each request toward the model that provides the appropriate balance of predictive quality, latency, reliability, and cost. ML model routing therefore represents a shift from static model deployment toward adaptive intelligence, where model selection itself becomes an important part of the machine-learning system.
Frequently Asked Questions
1. What is ML model routing?
ML model routing is the process of dynamically selecting which machine-learning model should handle a particular request. The decision can consider input characteristics, model capabilities, confidence, latency requirements, infrastructure conditions, cost, and business priorities.
2. Why would a production system need multiple ML models?
Different models can perform better for different types of requests, data segments, latency requirements, or computational constraints. Maintaining multiple specialized models allows a production system to use the appropriate level of model capacity instead of forcing every request through one model.
3. How does dynamic model routing differ from traditional model deployment?
Traditional deployment generally assigns a model to a workload statically, while dynamic routing allows the production system to make model-selection decisions at request time. This enables computational resources and model capabilities to adapt to individual request requirements and changing system conditions.
4. What signals can an ML router use?
A router can use input features, metadata, data type, estimated complexity, model confidence, uncertainty, historical model performance, latency requirements, request priority, infrastructure utilization, and inference cost. The appropriate signals depend on the application and the available models.
5. What is a model cascade?
A model cascade is an architecture in which requests pass through progressively more capable models when earlier stages determine that additional computation is necessary. A lightweight model can handle routine cases while uncertain or difficult requests are escalated to more expensive models.
6. How does confidence-based model routing work?
A routing system can use the confidence or uncertainty of an initial model prediction to decide whether additional processing is required. When confidence falls below an appropriate threshold, the request can be routed to a larger, specialized, or more accurate model.
7. Can confidence alone determine the correct model route?
Confidence alone may not be sufficient because model confidence can be poorly calibrated or misleading for inputs outside the training distribution. Production routing can become more reliable by combining confidence with uncertainty estimates, input characteristics, historical error patterns, and distribution-shift signals.
8. What is latency-aware model routing?
Latency-aware routing considers the response-time requirements of a request when selecting a model. A faster model may be preferred when a request has a tight deadline, while a higher-capacity model may be selected when the system has sufficient time and its additional quality justifies the extra computation.
9. What is cost-aware model routing?
Cost-aware routing incorporates the computational and infrastructure cost of each candidate model into the selection decision. Expensive models can be reserved for requests where their additional predictive value is meaningful, while less demanding requests are directed toward cheaper models.
10. What happens when the preferred model is unavailable?
Production systems can use fallback models when the preferred model is overloaded, unavailable, incompatible with the request, or too slow to meet the latency objective. Fallback strategies help maintain service availability and can provide graceful degradation rather than allowing a single model failure to interrupt the entire application.
11. Can model routing improve inference costs?
Yes, routing can reduce inference costs by sending routine or low-complexity requests to smaller and less expensive models while reserving high-capacity models for cases that require them. The overall savings depend on request distribution, model costs, routing overhead, and how effectively the routing policy identifies appropriate cases.
12. What is a learned model router?
A learned router is an ML component that predicts which candidate model is likely to provide the best outcome for a particular request. It can learn from historical information about model quality, latency, cost, input characteristics, and other contextual signals instead of relying exclusively on manually defined routing rules.
13. What are the risks of learned model routing?
A learned router can become outdated when models, user behavior, data distributions, or infrastructure conditions change. It can also inherit biases from historical routing data, making continuous evaluation and monitoring necessary to ensure that routing decisions remain appropriate.
14. How should ML engineers monitor a routing system?
Engineers should monitor traffic distribution across models, model-level quality, latency, escalation rates, error rates, resource utilization, routing decisions, and cost. Segment-level monitoring is also important because aggregate metrics can hide poor routing or degraded model performance for particular types of requests.
15. Will ML model routing become part of standard ML platforms?
Model routing is likely to become increasingly integrated into ML serving platforms as organizations operate larger portfolios of models. Shared platforms can provide common capabilities for model registration, routing policies, traffic allocation, fallbacks, experimentation, observability, version management, and cost-aware optimization, reducing the need for every product team to implement these capabilities independently.